Main findings
We note the following results:
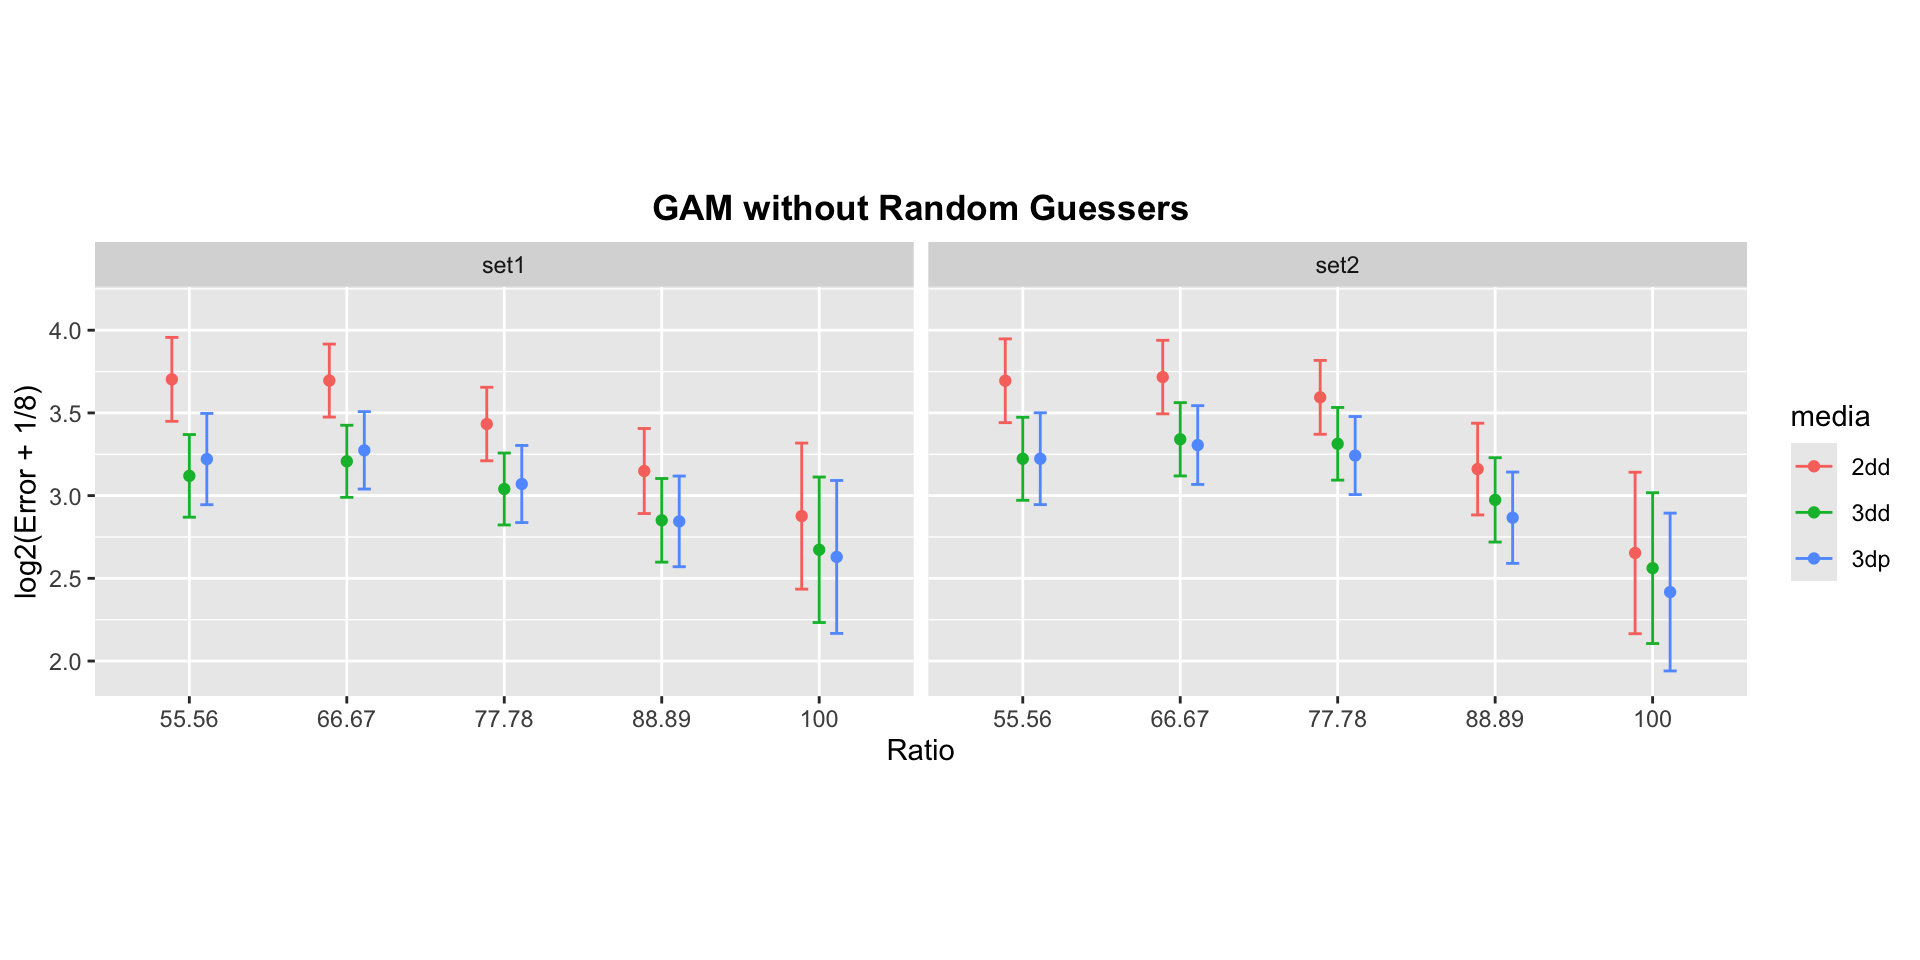
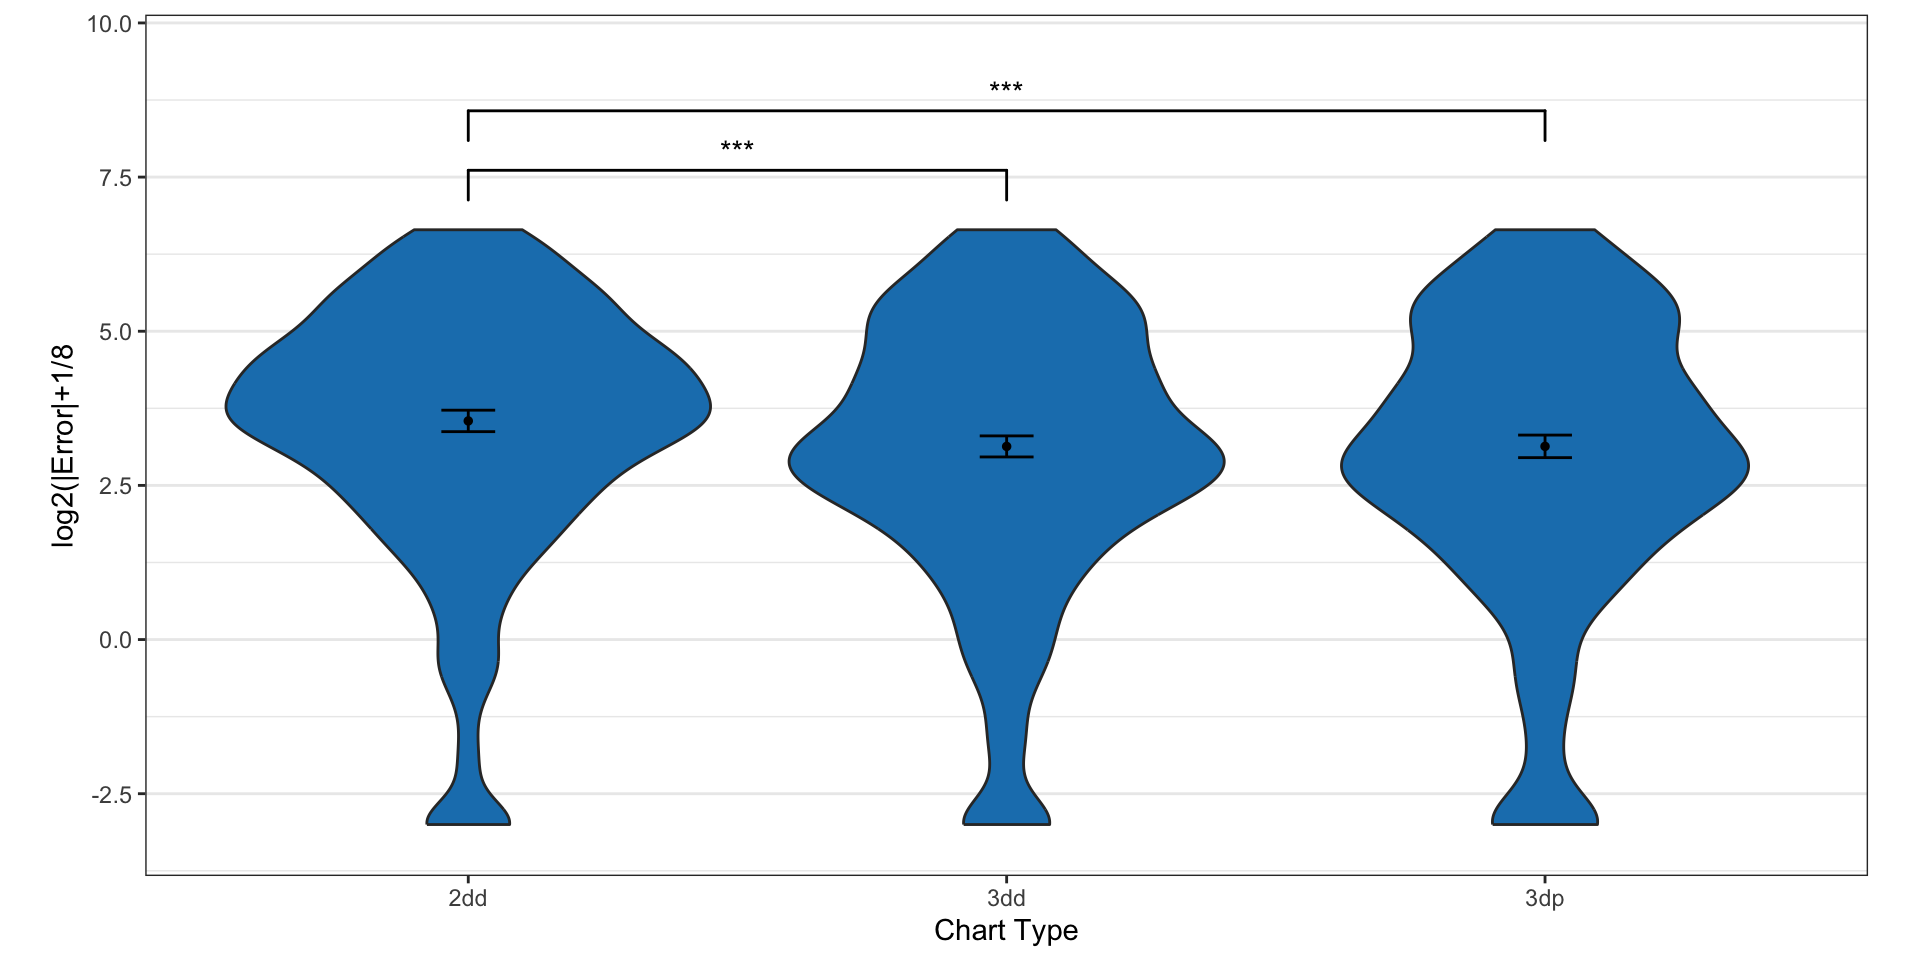
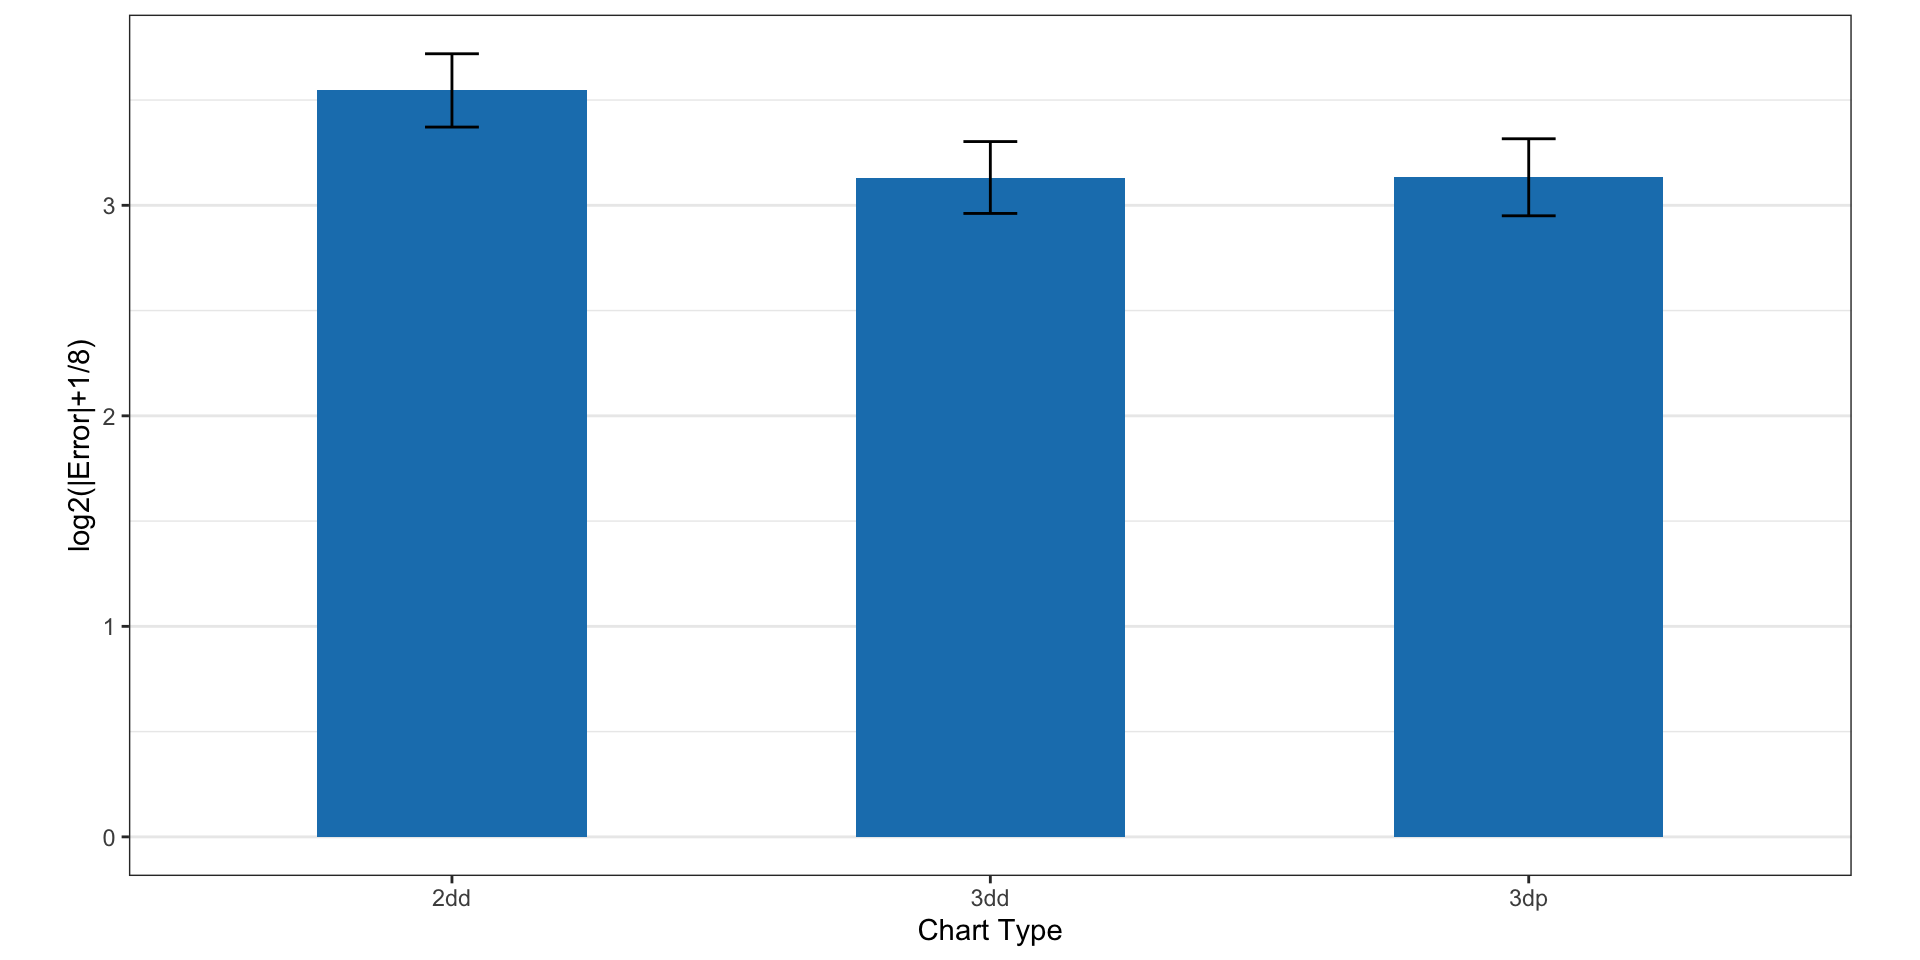
- Digital and physical 3D heat maps produced lower error than 2D heat maps
- No detectable differences between digital and physical 3D heat maps
- Differences attributed to dataset and stimuli pair
Ph.D. Final Examination
April 17, 2026
Data is everywhere, but how do we communicate it through visualizations? We design graphics to account for:
Many types of charts exist for displaying different types of data.
What alternative methods can we use to better display it?
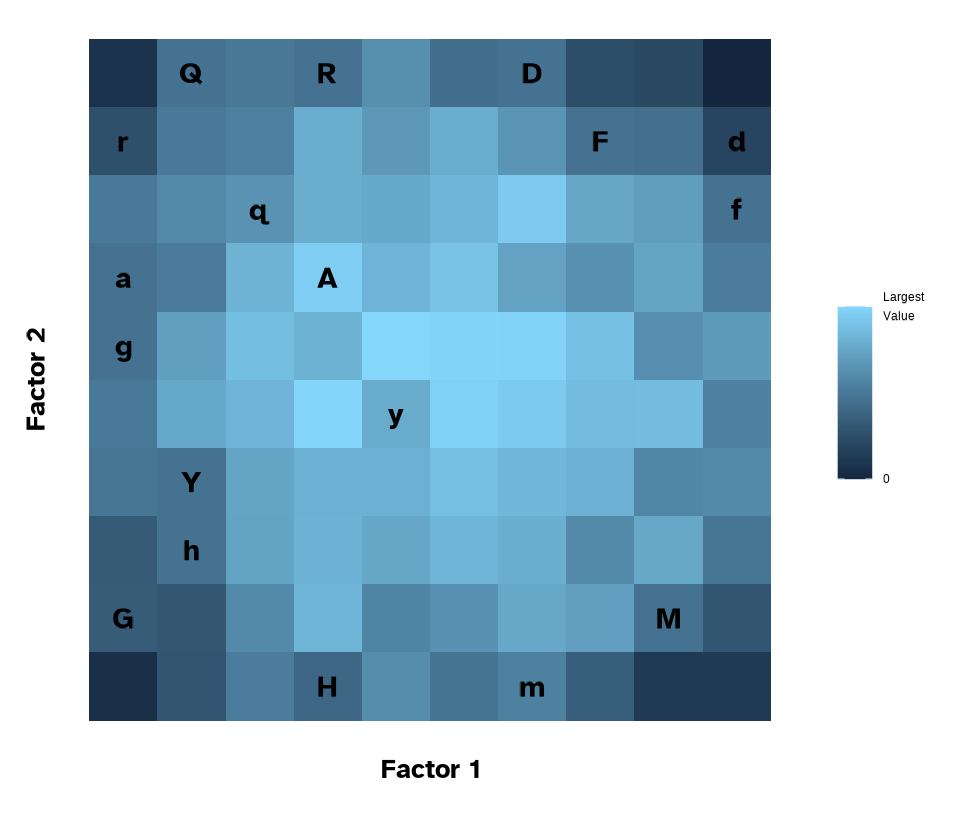
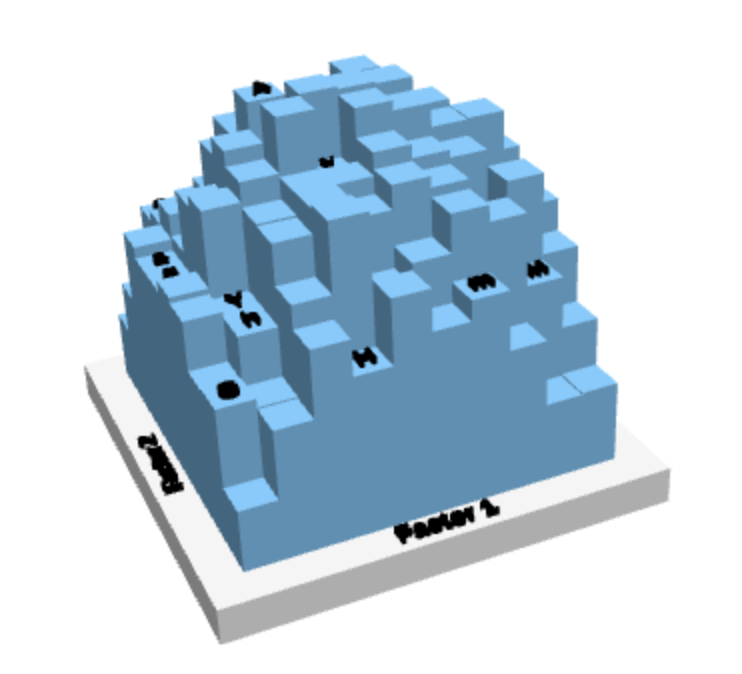
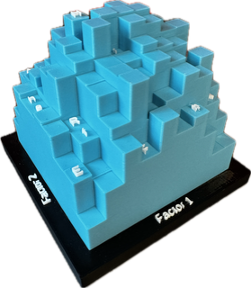
Heat maps are a type of data visualization that convey data in three dimensions.
Two dimensions represented by spatial coordinates
Other dimension (typically a continuous response variable) represented by alternative visual encoding
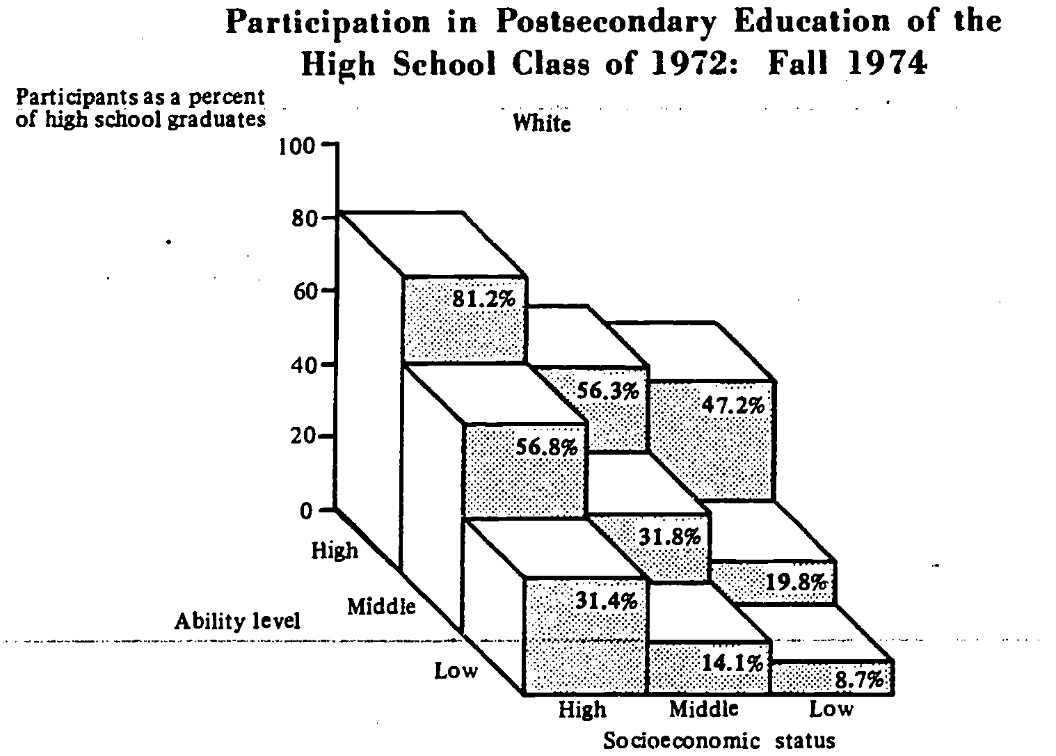
Many advancements in technology have allowed for greater artistic creativity in displaying data.
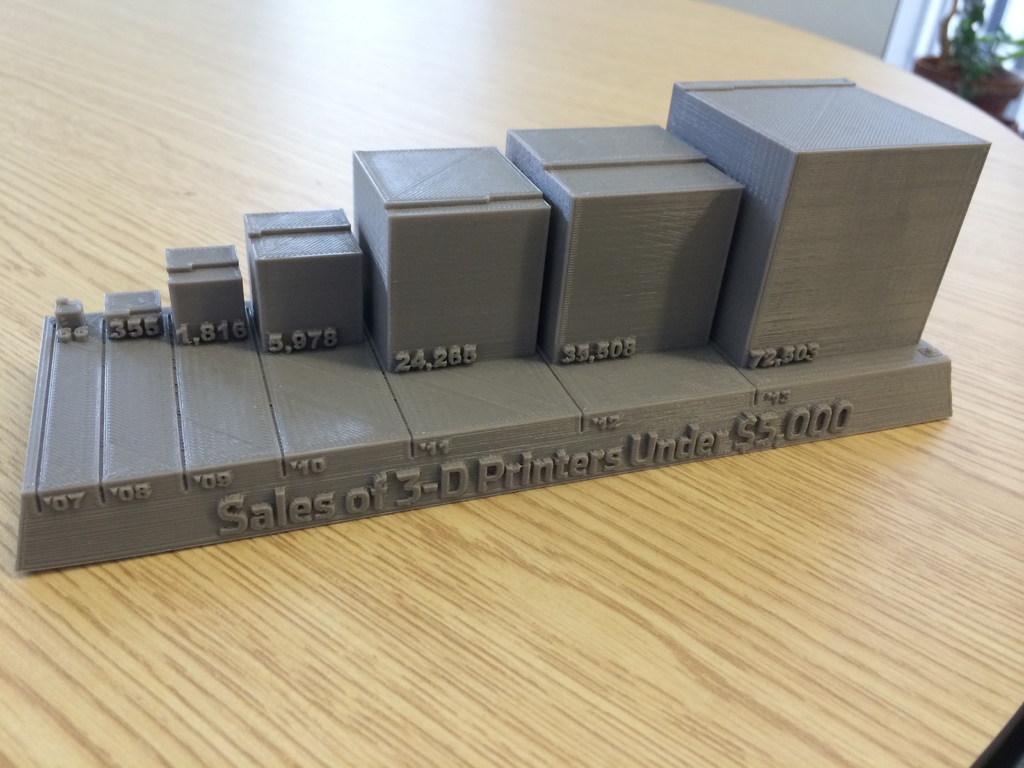
What are the potential benefits of using 3D-printed charts for statistical graphics?
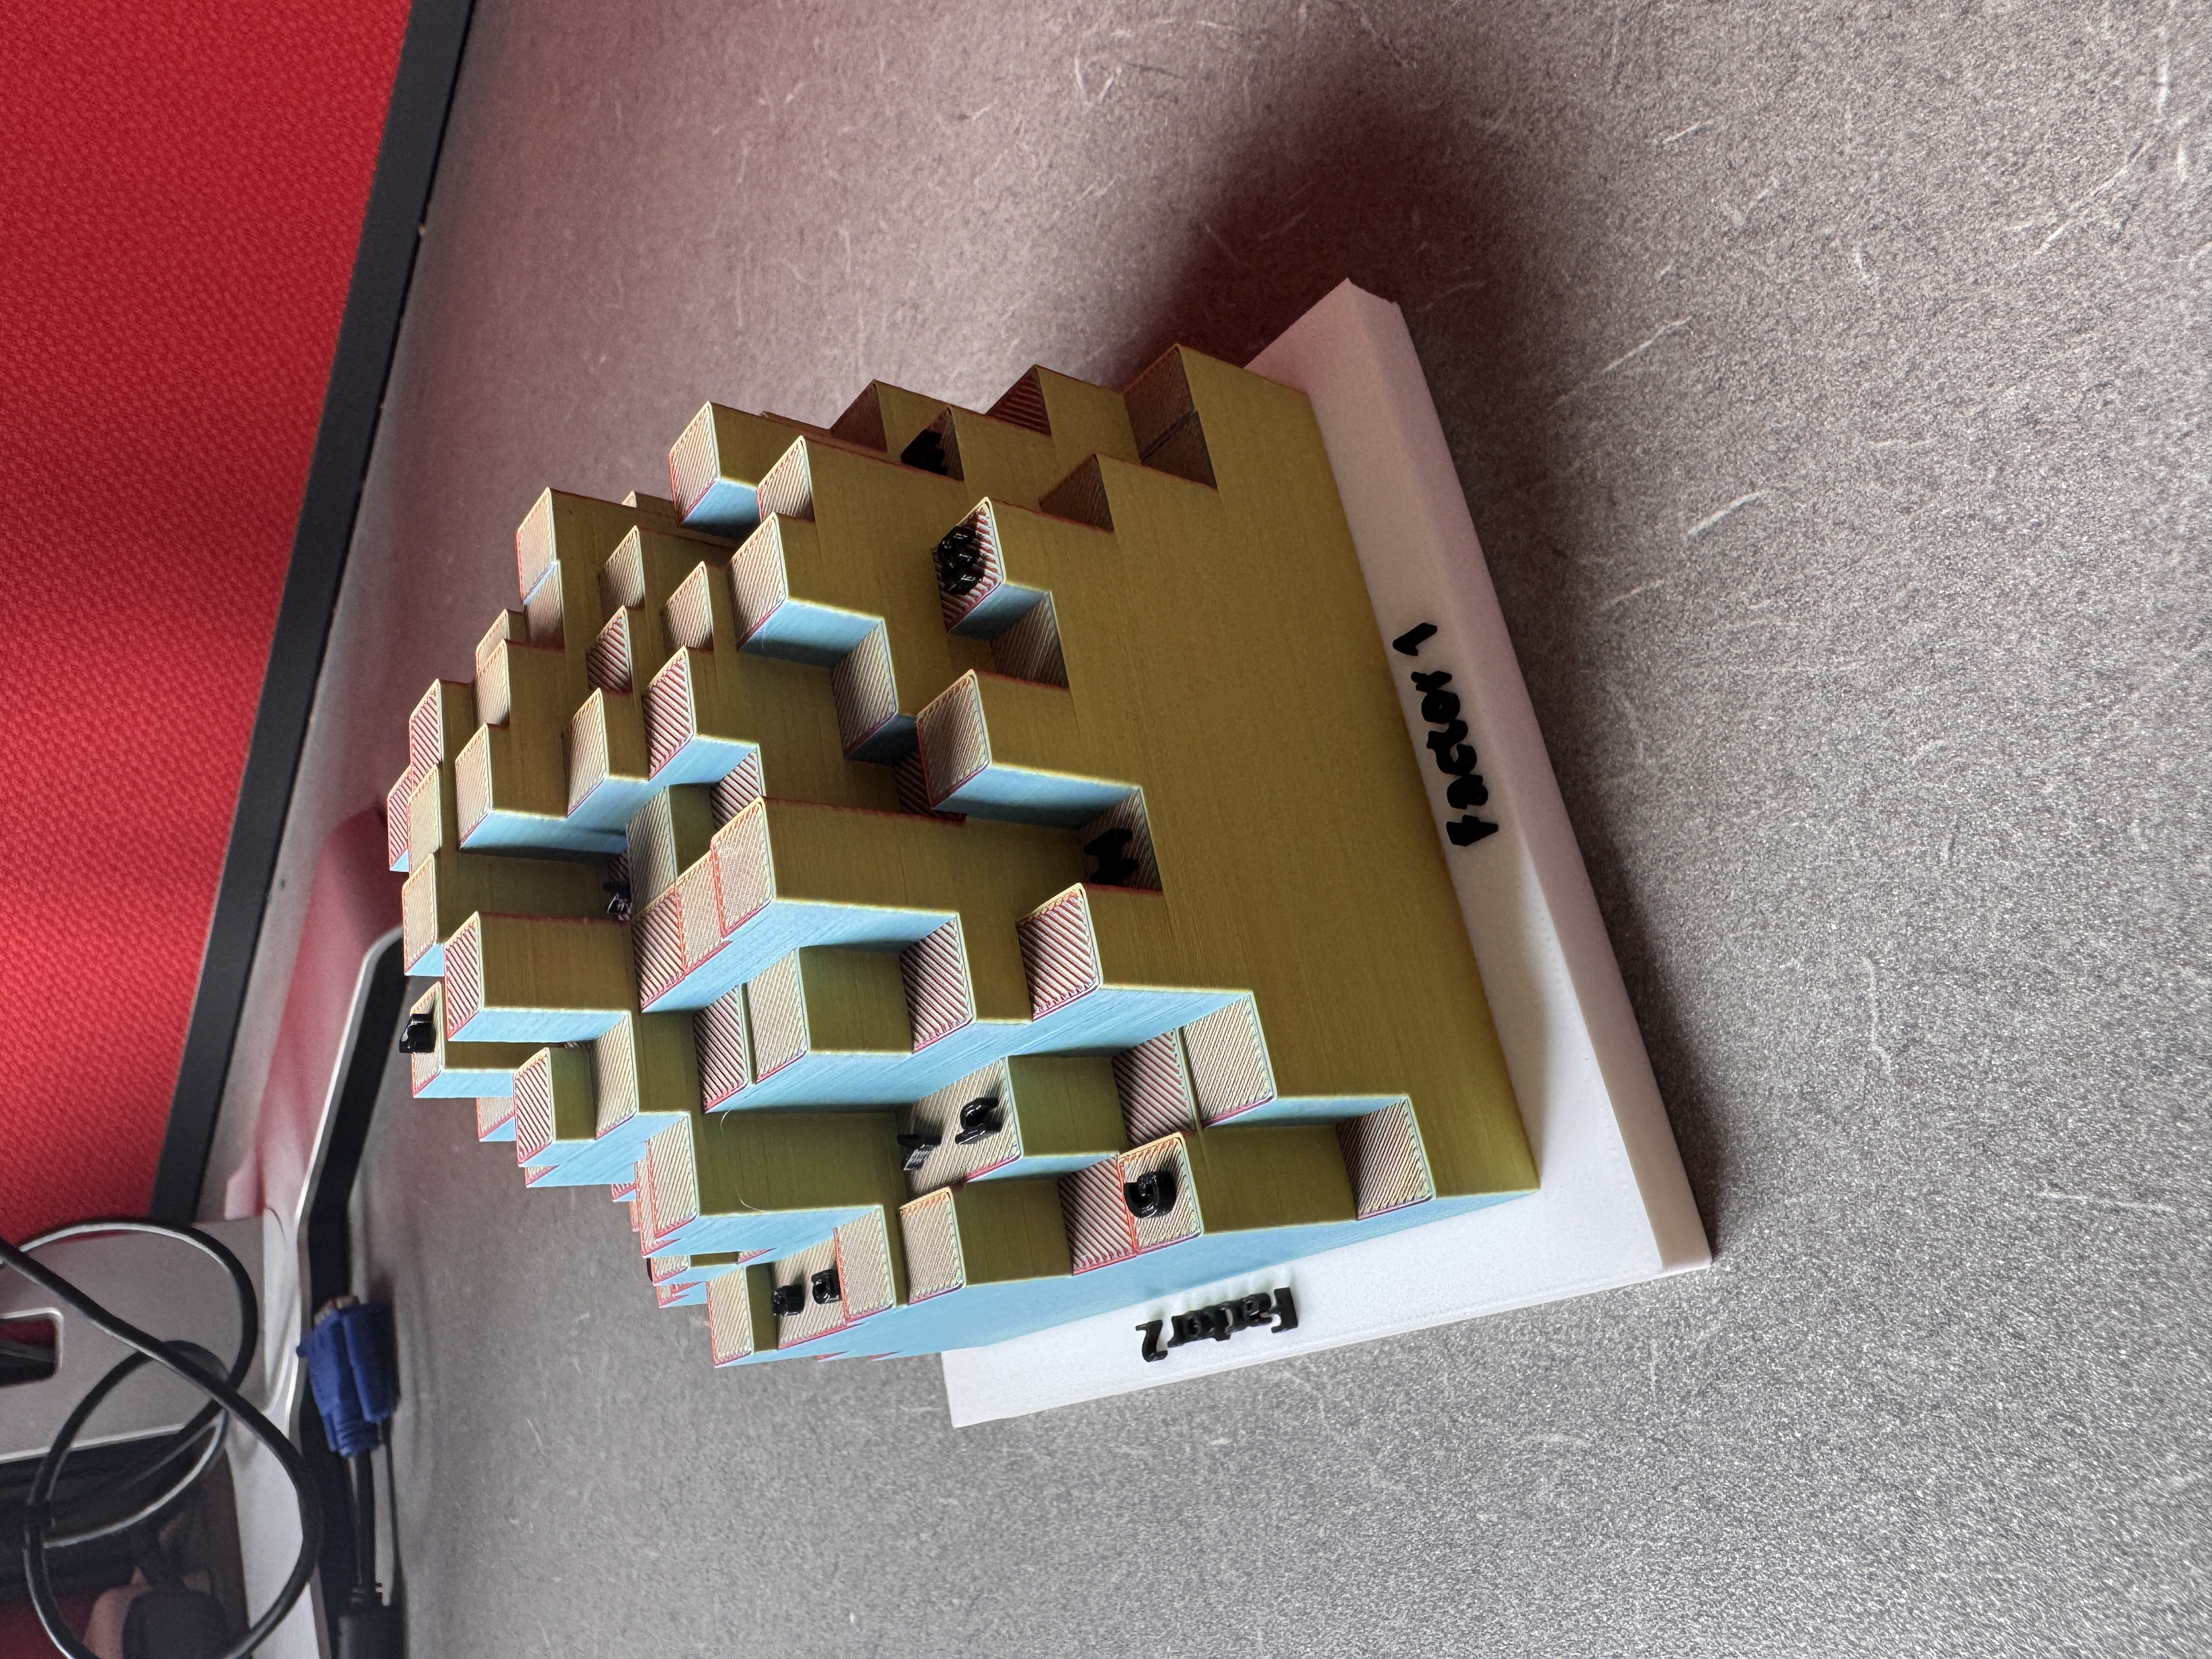
To date, very few empirical studies have been conducted using physical 3D charts.
Physical 3D heat maps suggested to be more efficient at estimations (\(n=16\)) (Jansen, Dragicevic, and Fekete 2013)
Physical bar charts may be more memorable than digital charts (\(n=40,16\)) (Stusak, Schwarz, and Butz 2015; Stusak, Hobe, and Butz 2016)
Some studies show smaller error rates for 3D charts using virtual reality (e.g., Kraus et al. 2020)
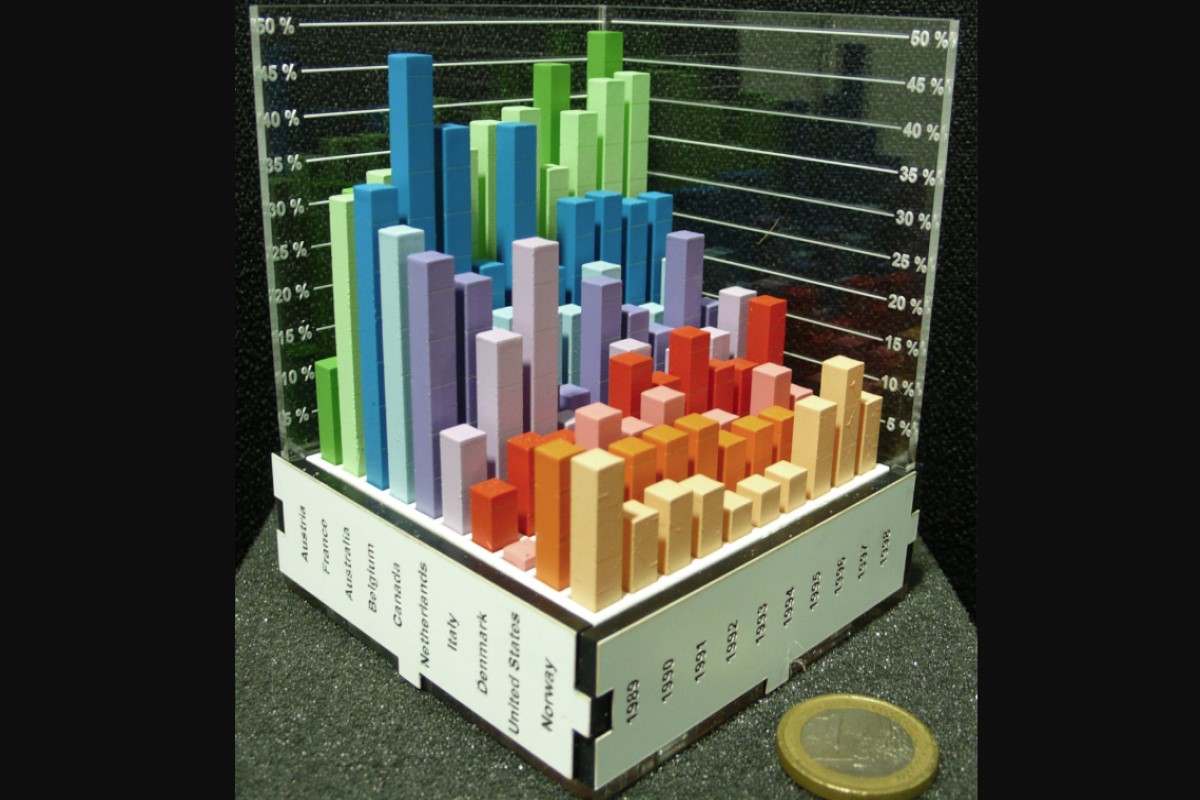
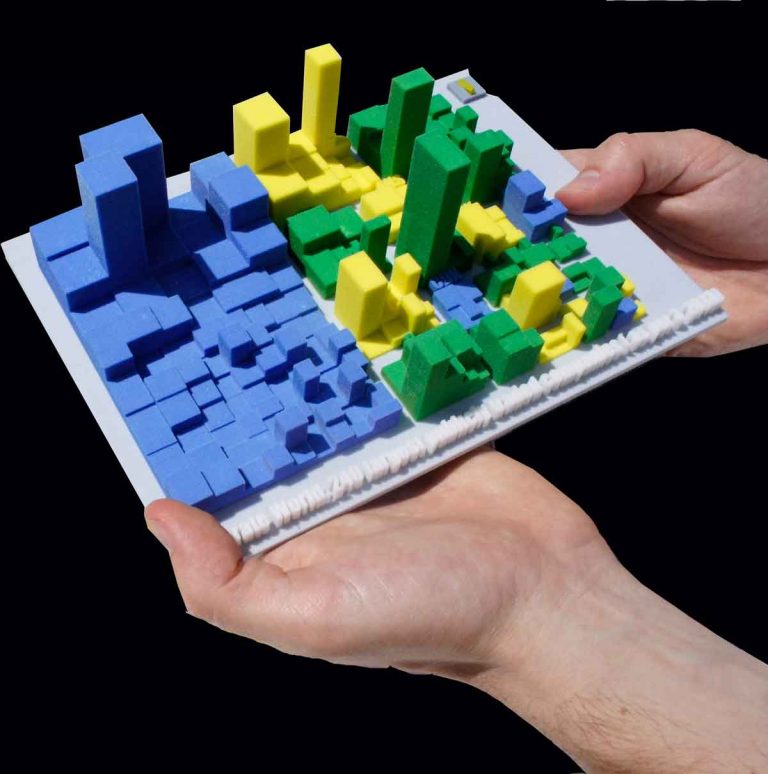
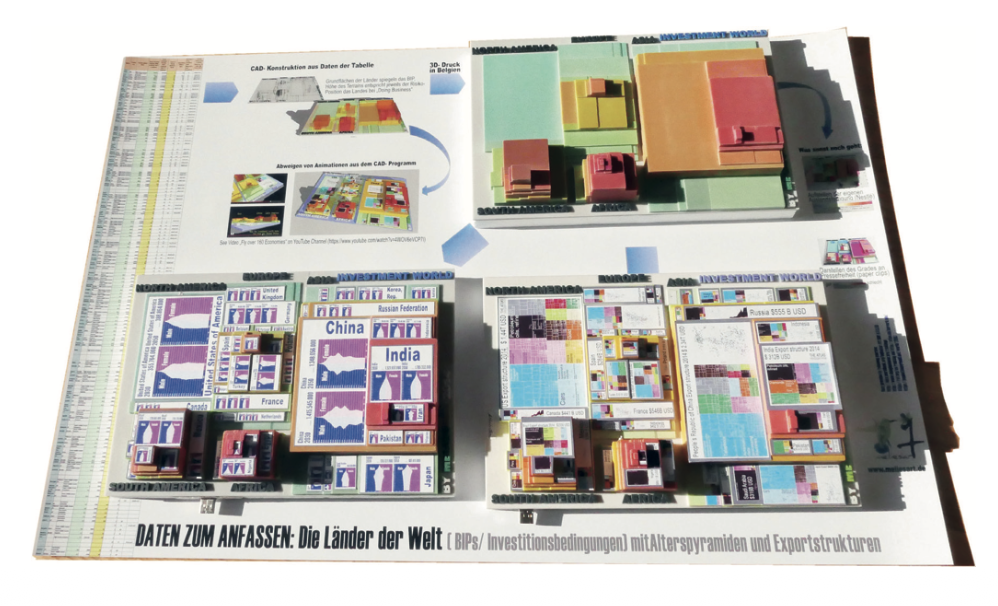
Many instances of 3D-printed charts are created for artistic representations!


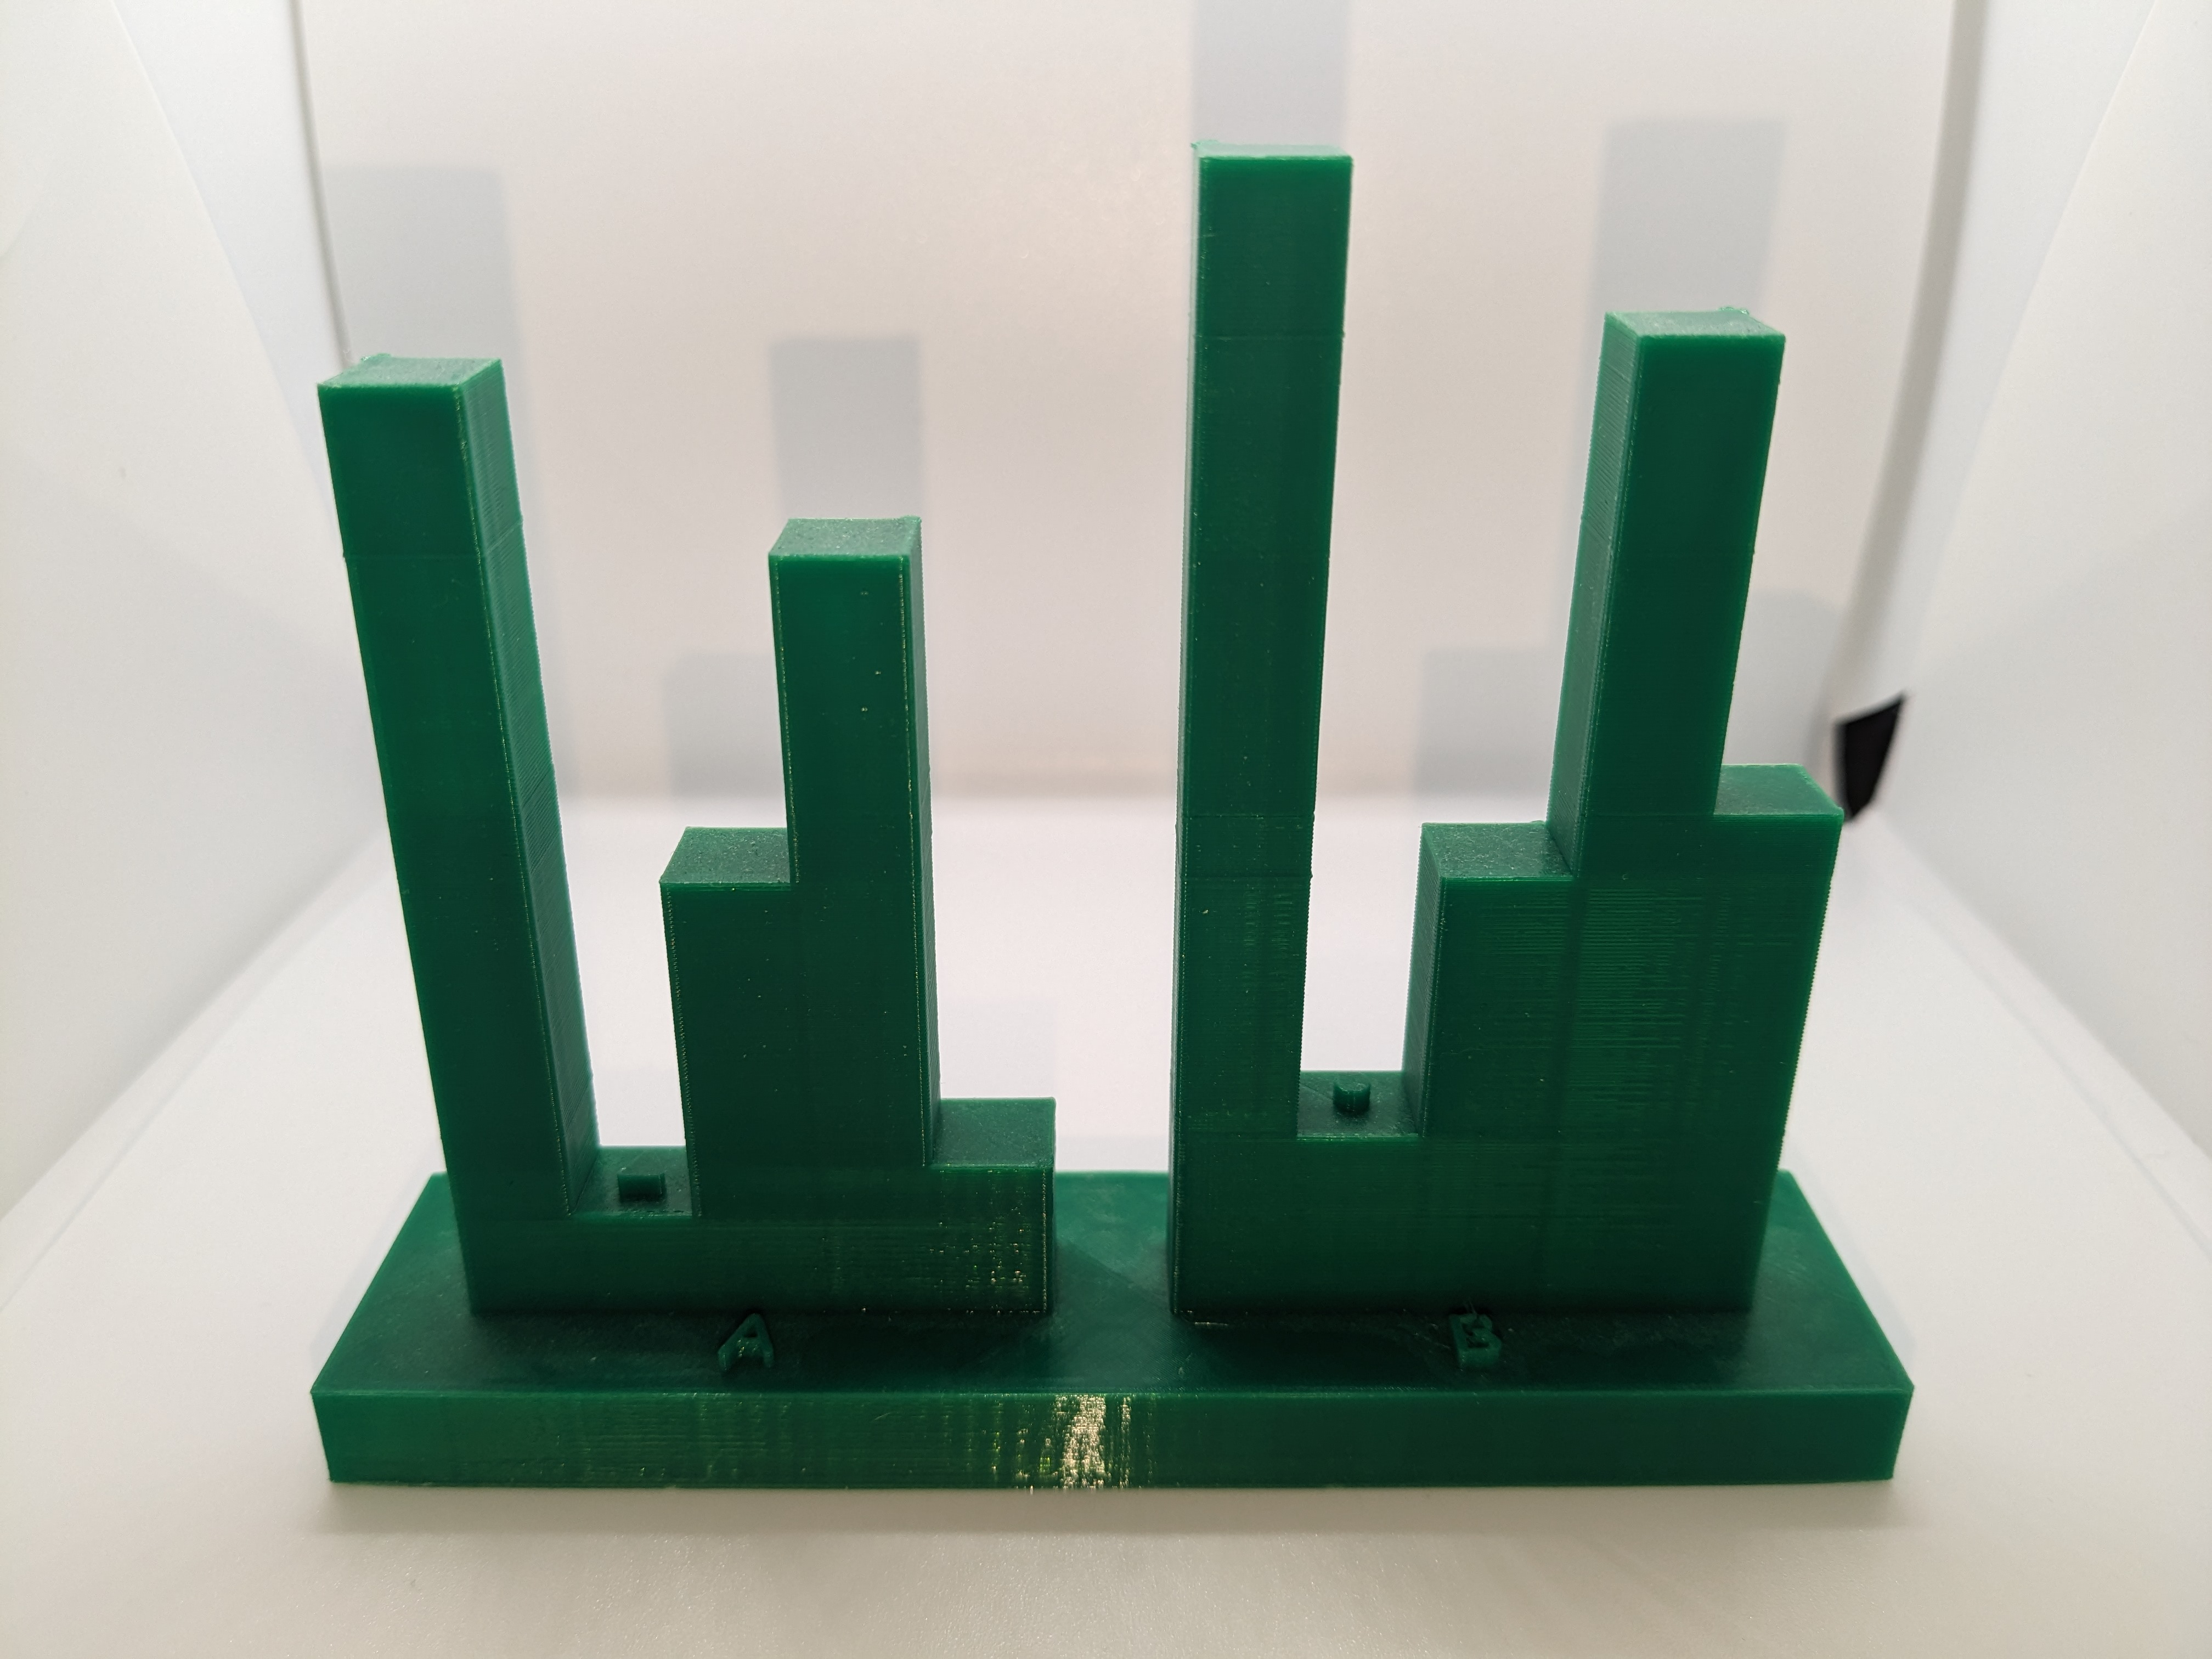
Examples of 3D-printed charts
Previous research suggests that 3D charts may perform better when all three dimensions are used for displaying information (Barfield and Robless 1989; Fisher, Dempsey, and Marousky 1997; Kraus et al. 2020).
Does this hold for numerical estimations from physical 3D heat maps compared to 2D static heat maps and interactive digital 3D heat maps?
There are many possible conditions for which charts can be rendered that could influence numerical estimations.
To what extent do underlying datasets and comparison types affect numerical estimations from these charts?
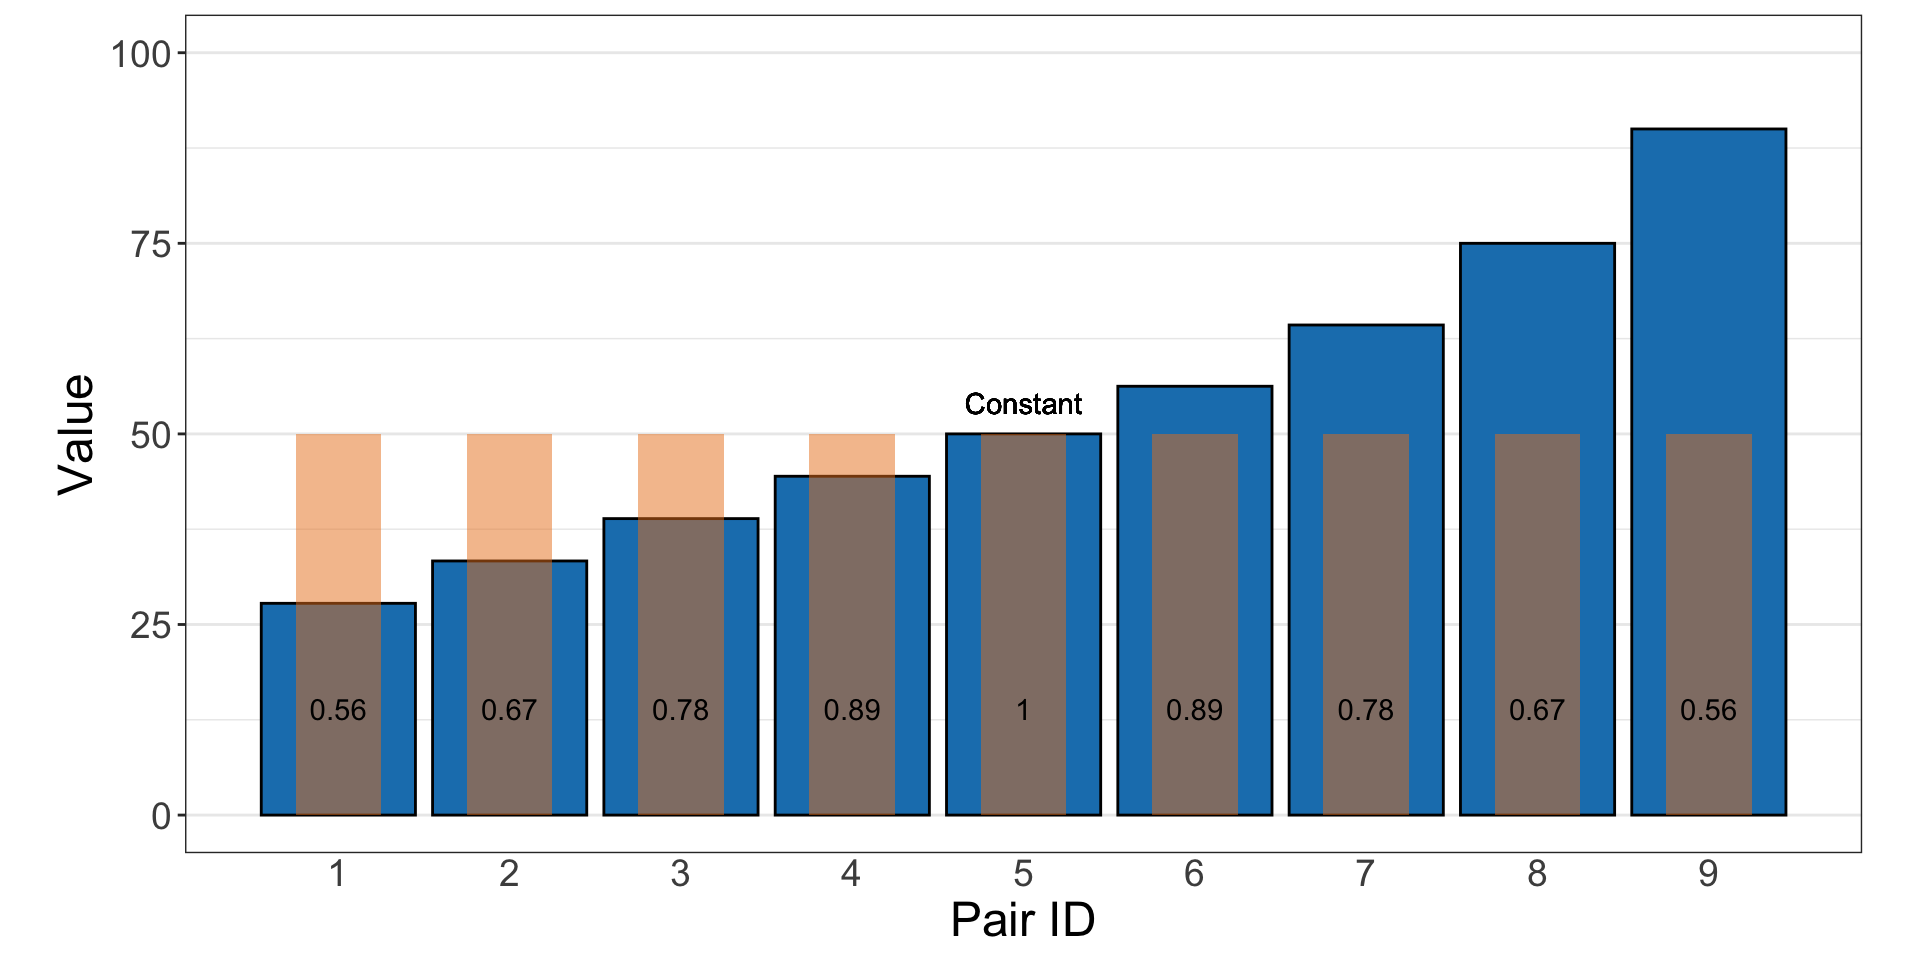
The design of the 3D heat map experiment uses the method of constant stimuli: ratios are estimated with respect to one stimuli height that remains the same.
\[ S=\text{Stimuli} \]
Setting 50 as the constant and 90 as the maximum, a sequence of stimuli are chosen by equally partitioning the ratios between \(50/50=1\) and \(50/90\approx0.556\). The same ratios are used when setting 50 as the maximum in the stimuli pair.
We used two datasets created using a mixture distribution for equations for spheres and random noise as a reference distribution. Final values were scaled between 0 and 100.
We strategically placed stimuli so that they looked natural with respect to the simulated dataset.
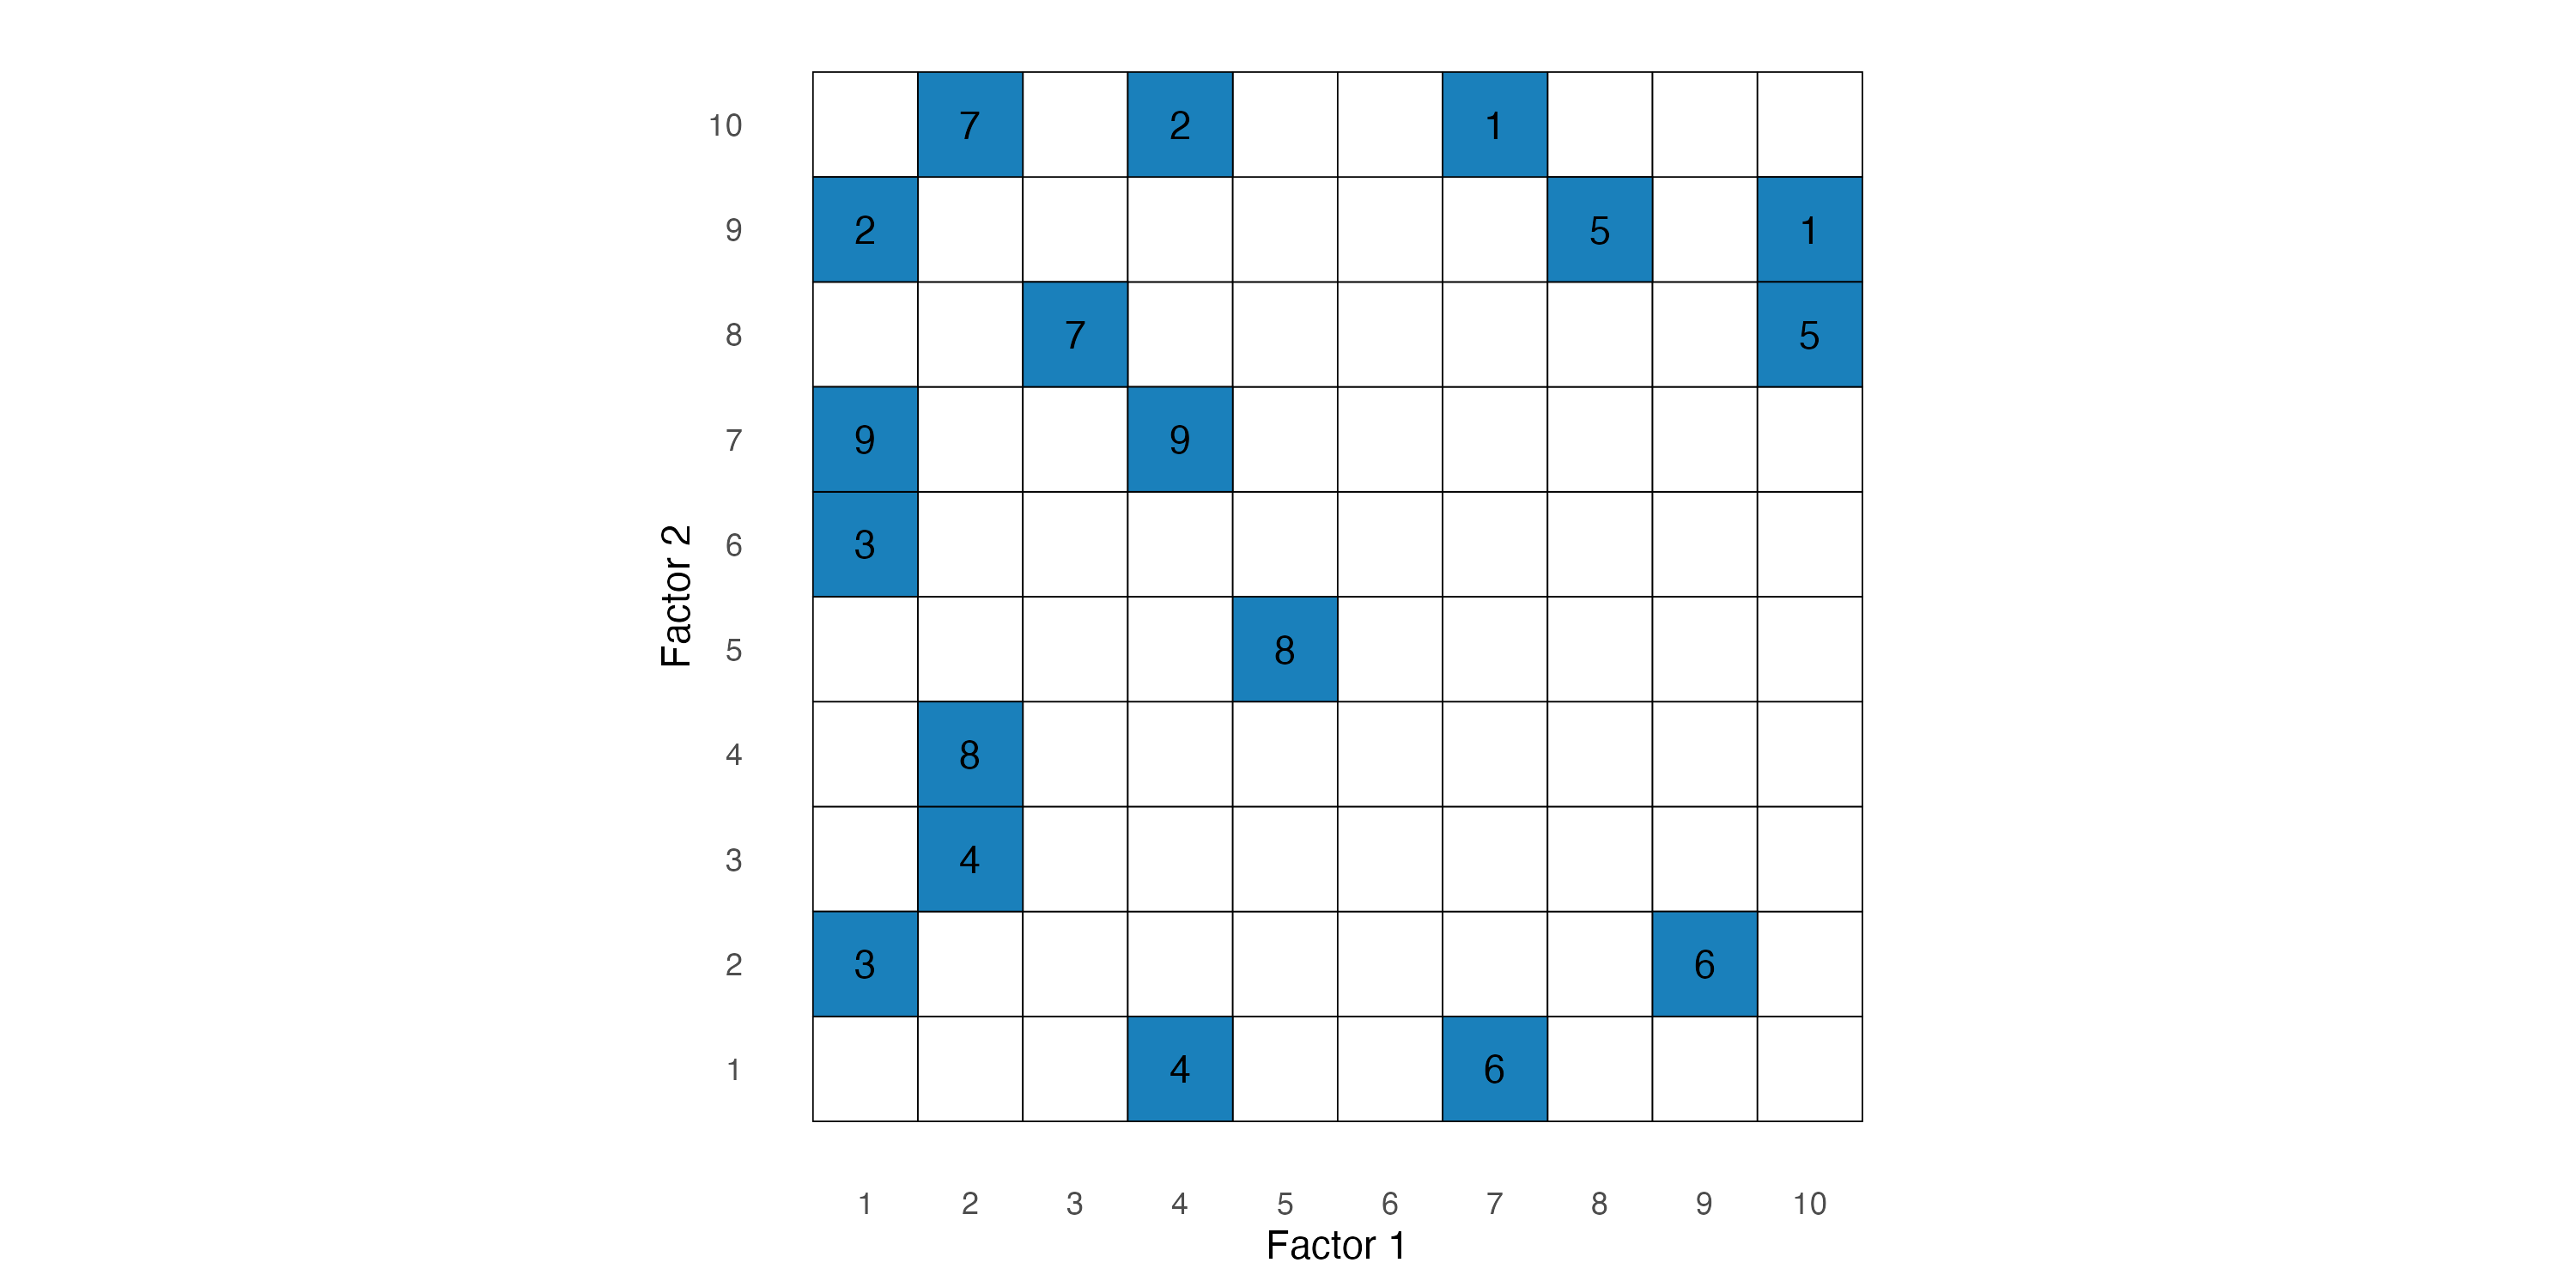
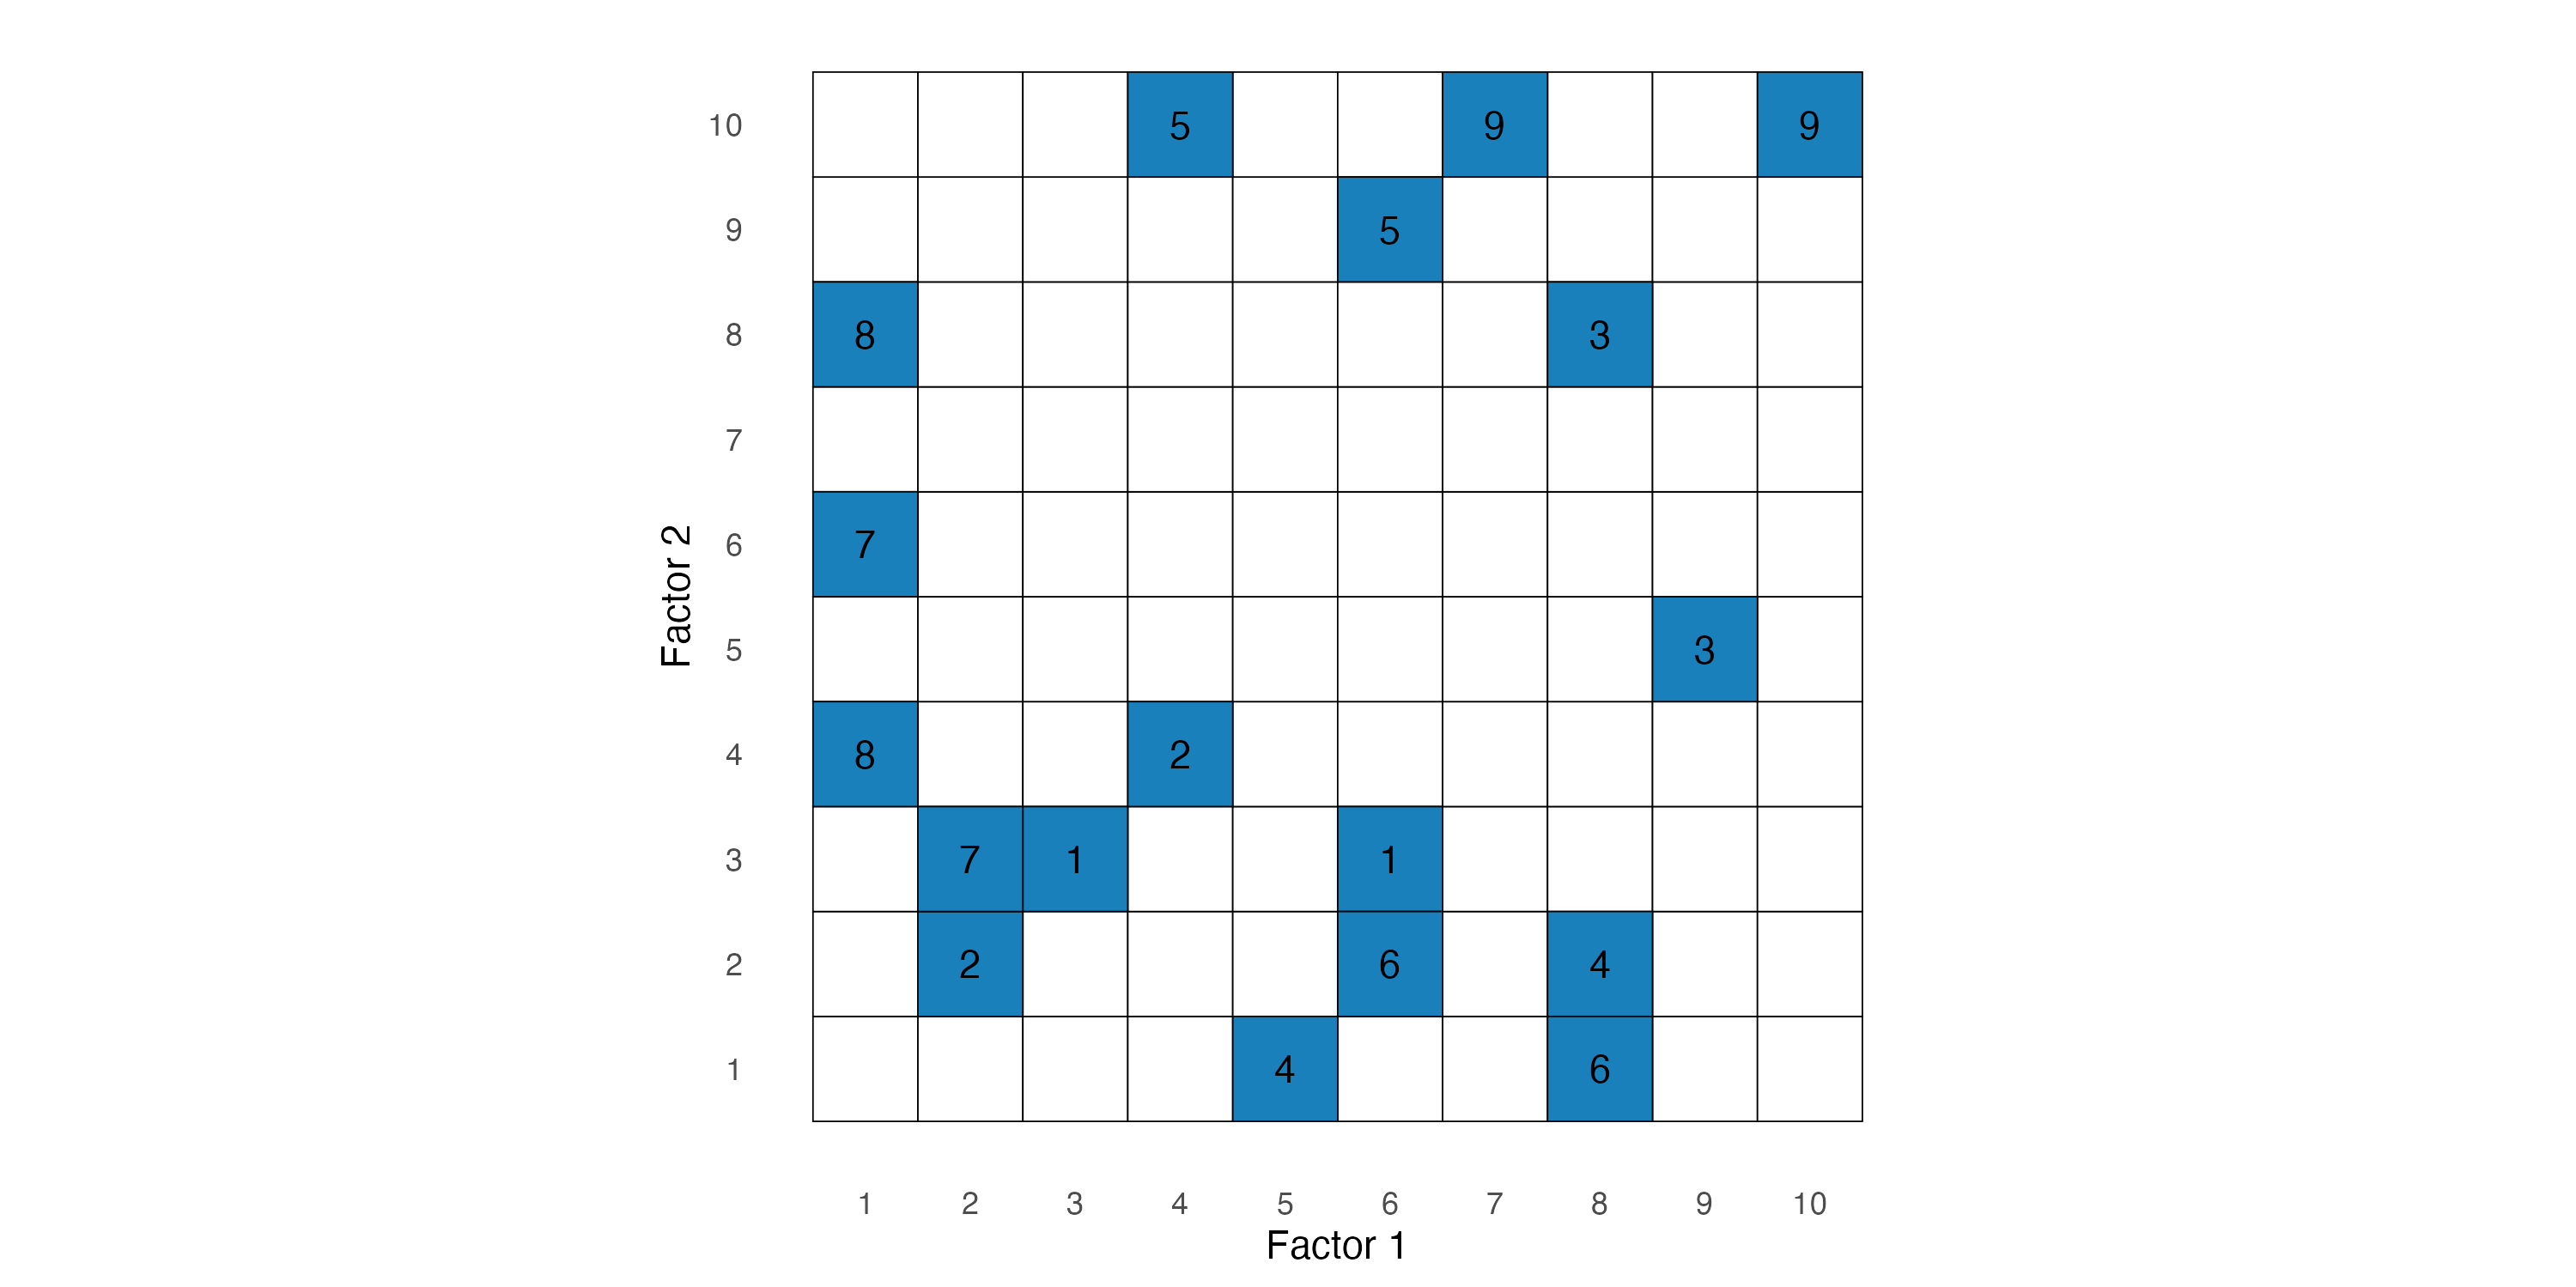
For a full replicate, there are \(3\times2\times9=54\) treatment combinations:
Way too many trials for a single participant’s attention span!
Our main interest is the difference between media types, measured at a given ratio and dataset. To accomplish this and to reduce the number of trials per participant, we use 4 of the 9 possible stimuli pairs to create blocks.
\[ 2\times3\times4=24 \]
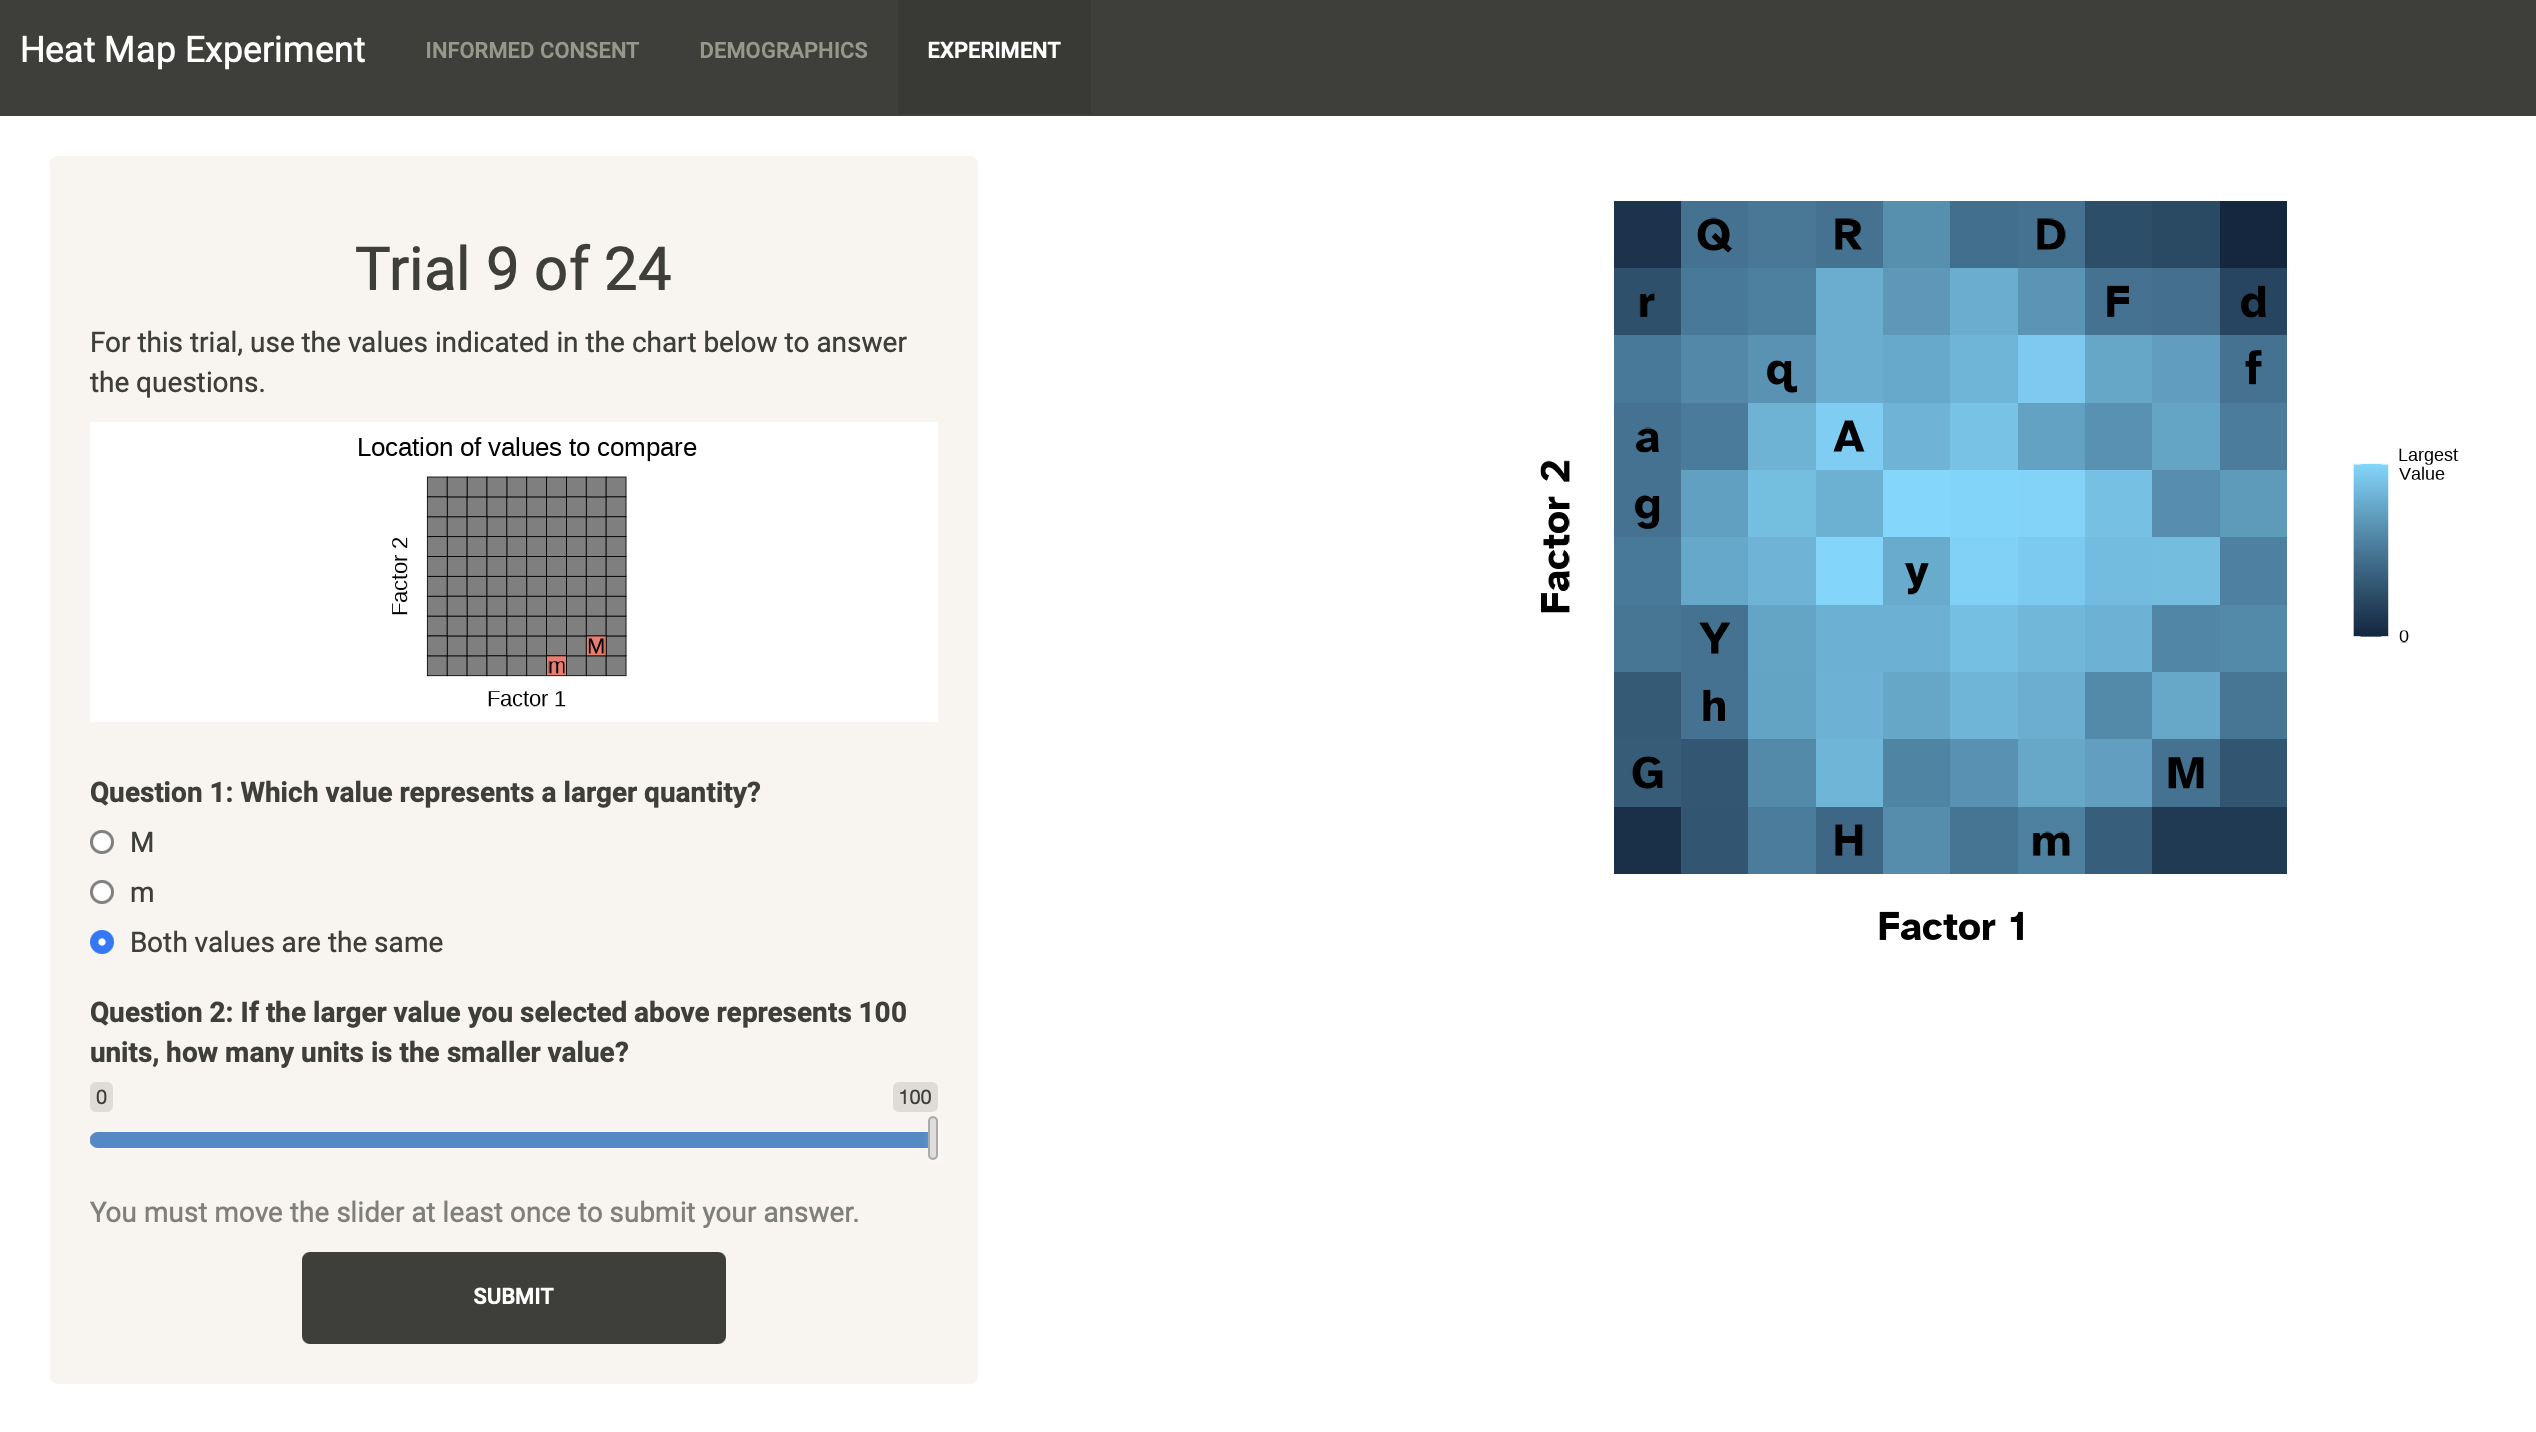
For each trial in the experiment, we ask two question adapted from Cleveland and McGill (1984).
Question 1 has three options: one for each value in the pair and one option for if the values are the same.
Question 2 has a slider ranging from 0 to 100, and the initial position is randomly positioned
Shiny application
We recruited our subjects by integrating an experiential learning project into the STAT 218 curriculum at UNL. The data collection period was from Summer 2025 to Fall 2025.
For data to be collected, students had to meet the following criteria:
Students were instructed to complete the experiment at communal office hour locations.
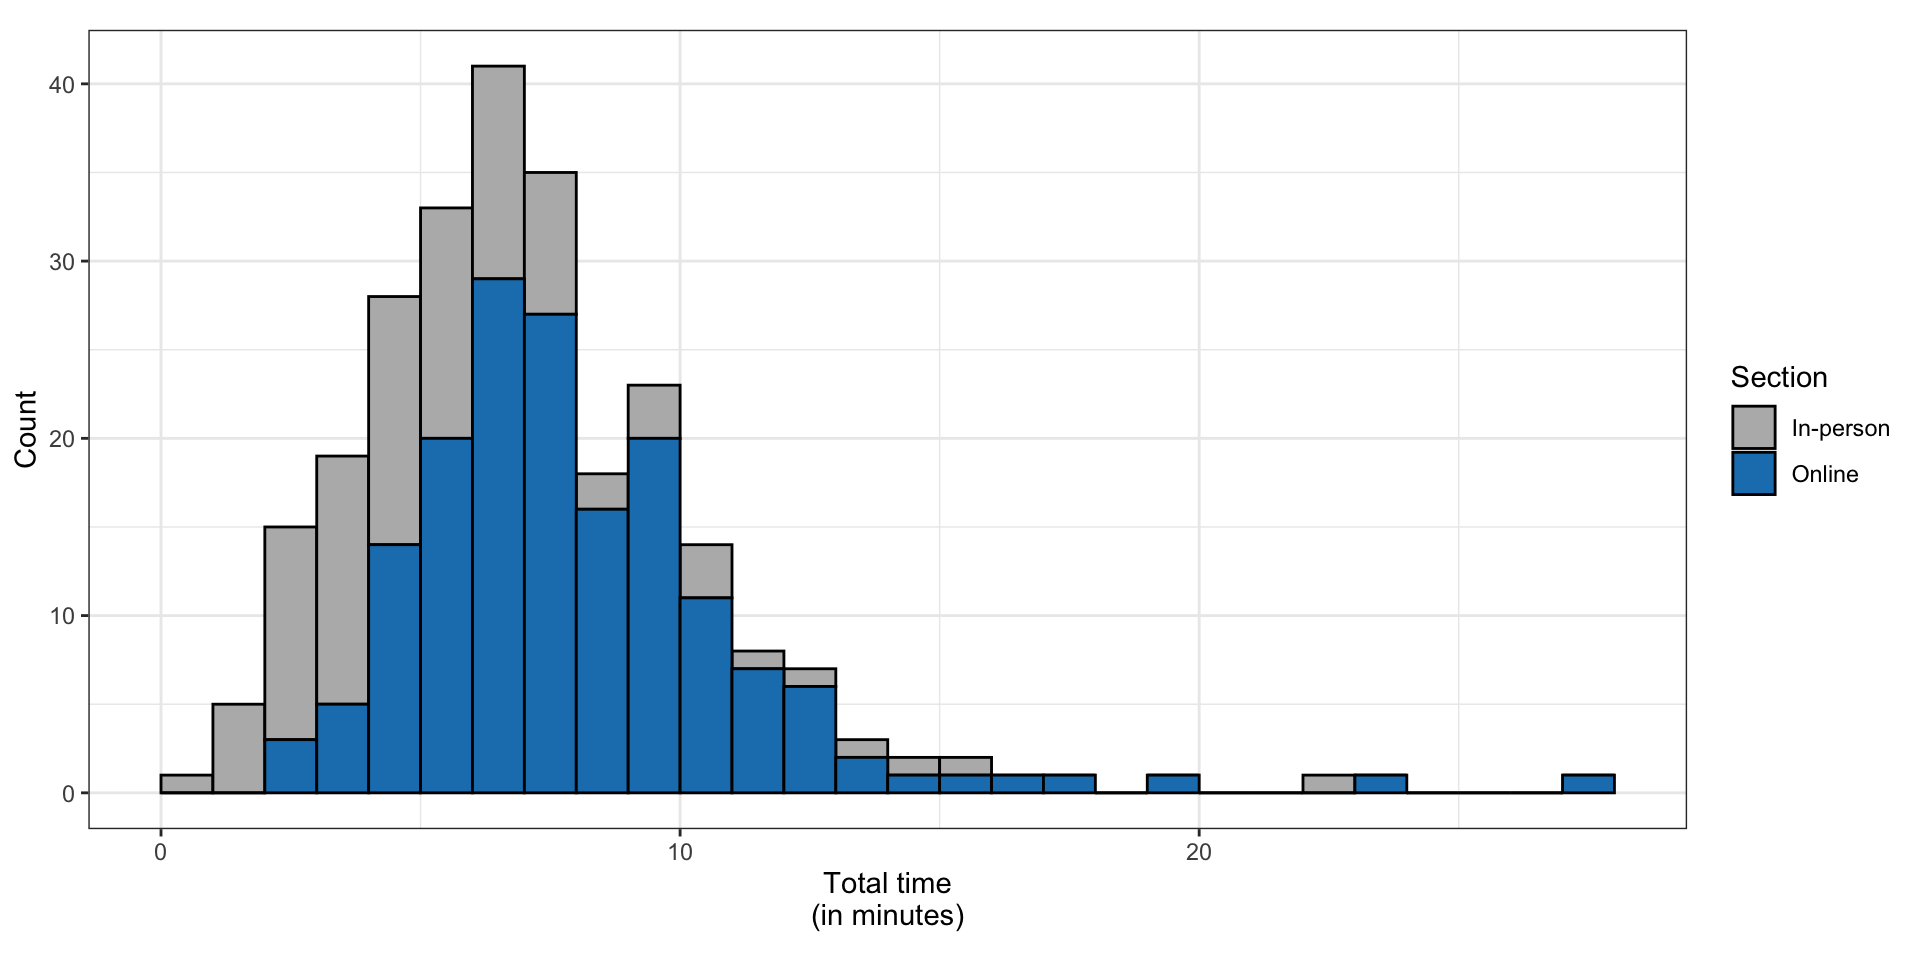
259 students completed the entirety of the experiment. Of these, 92 students were enrolled in online sections of the course.
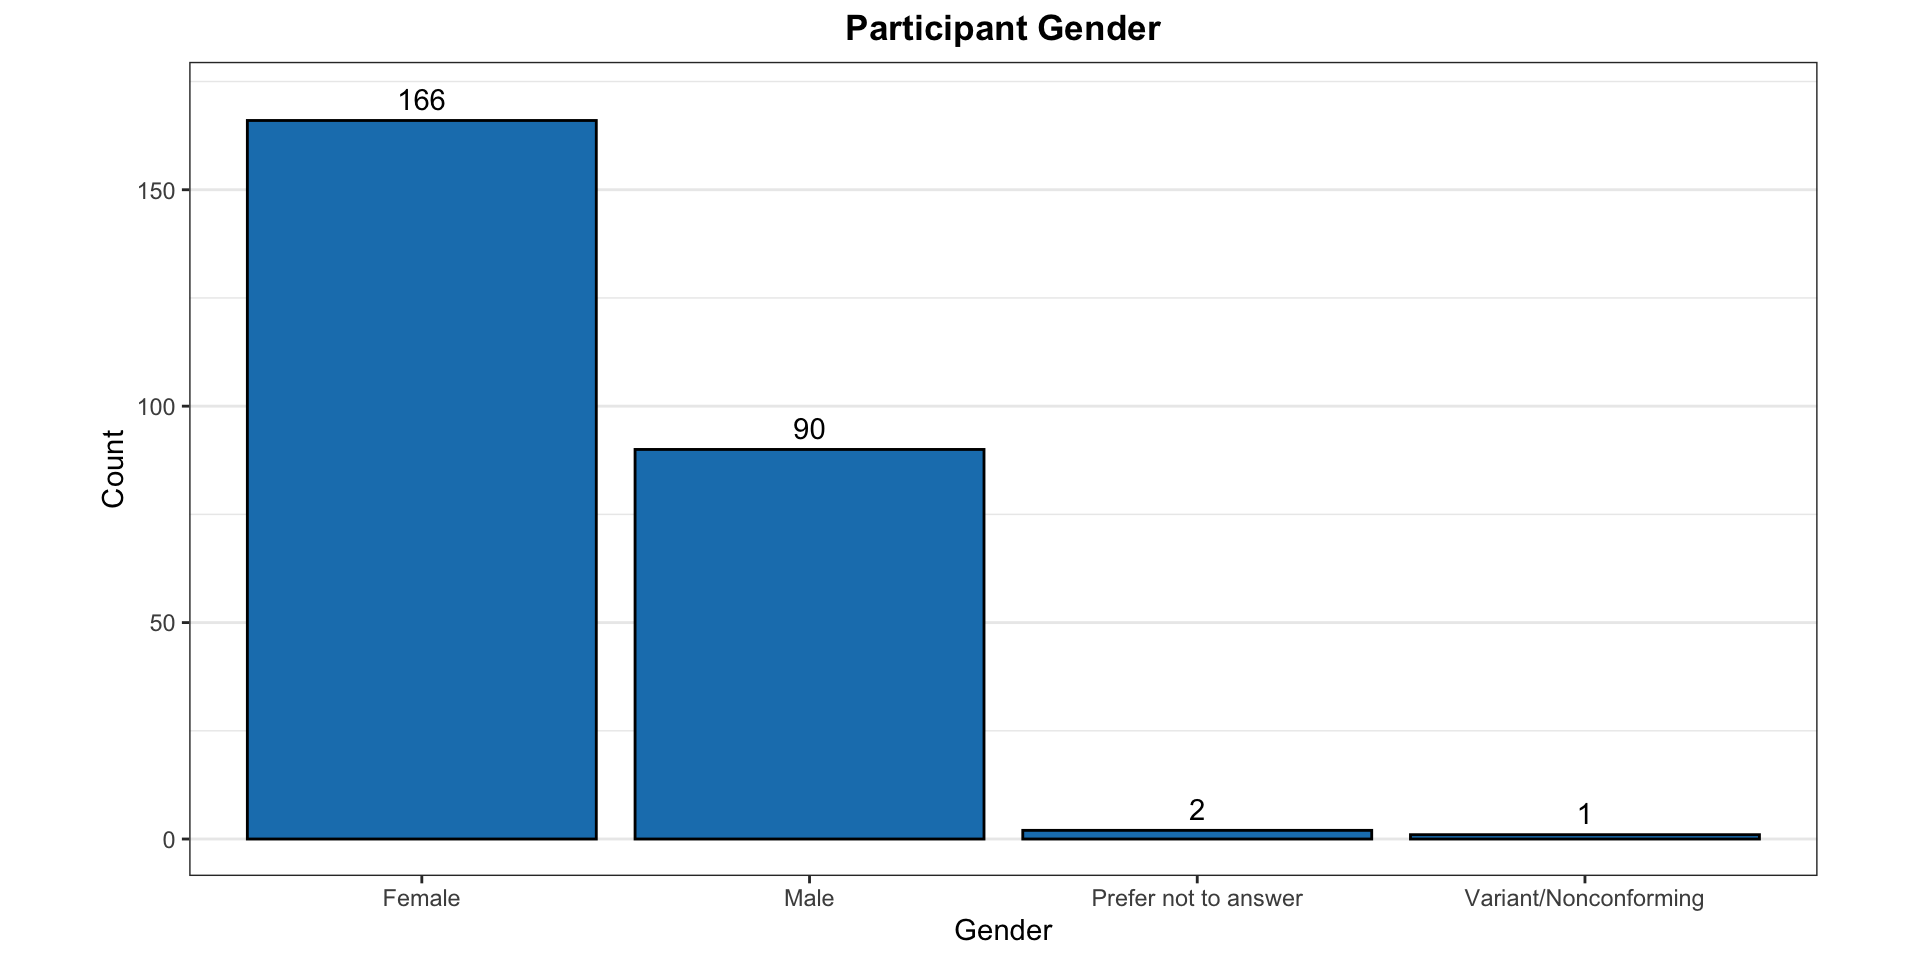
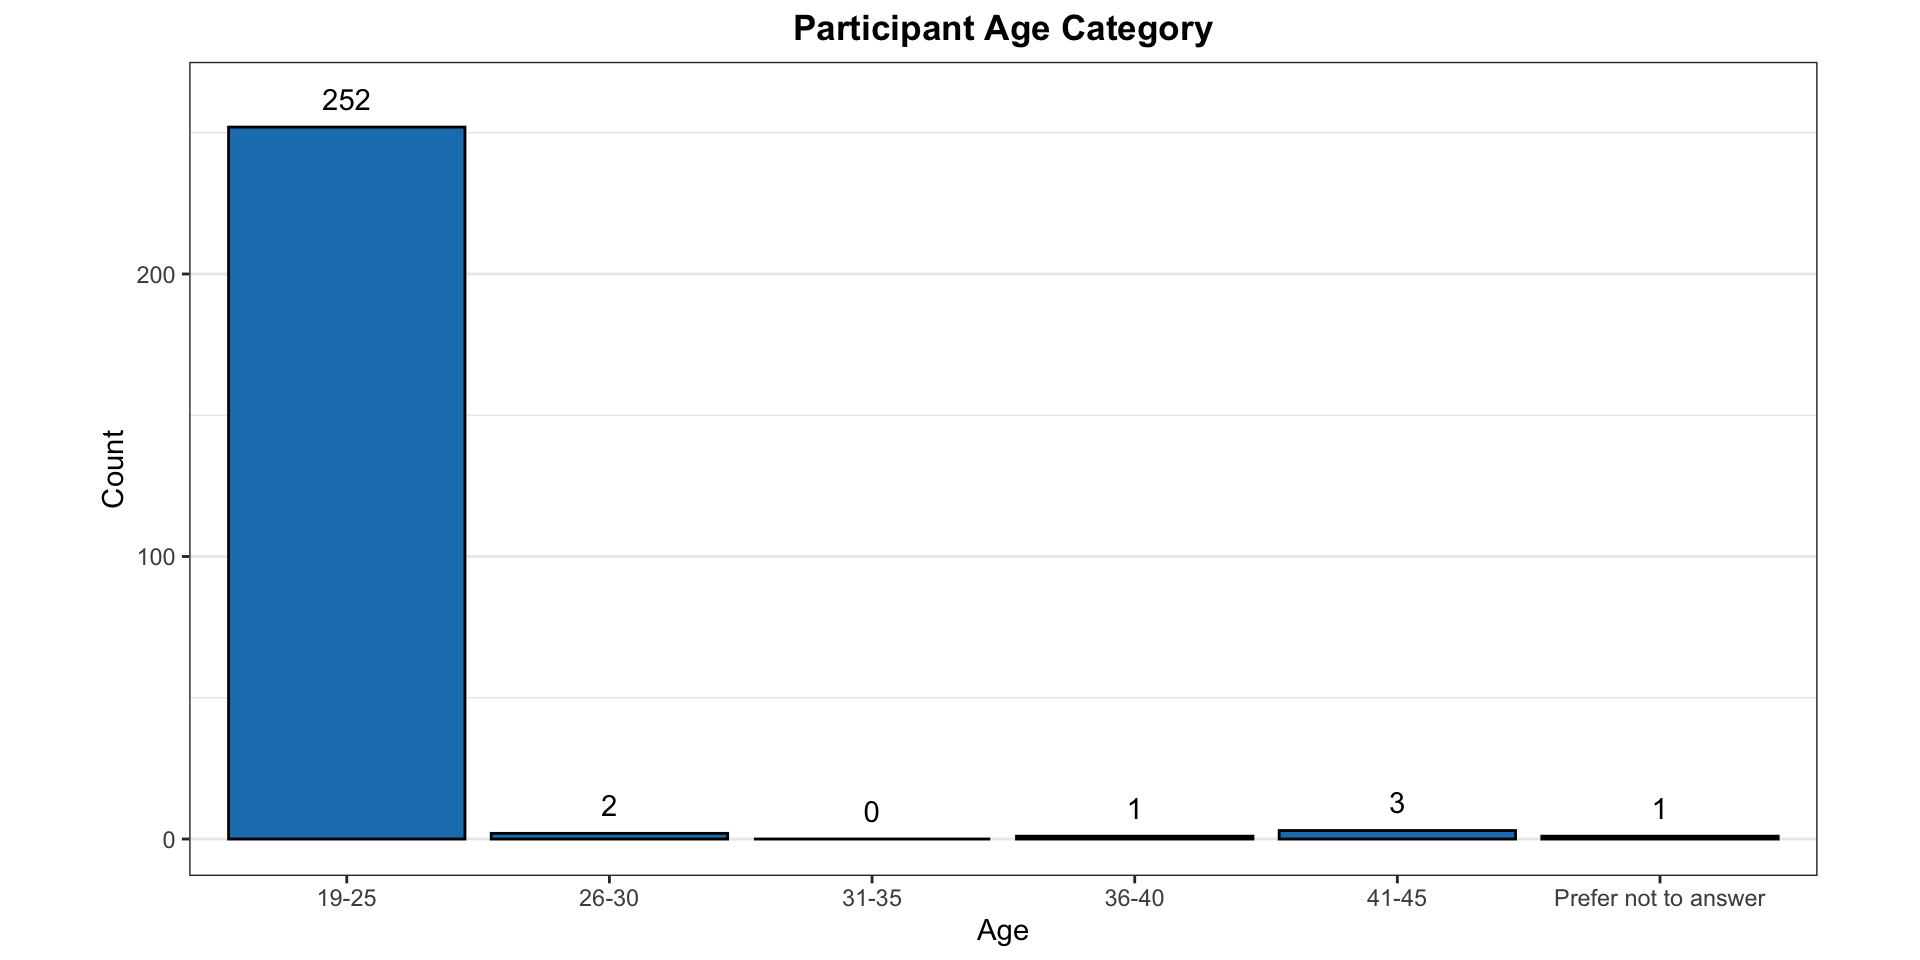
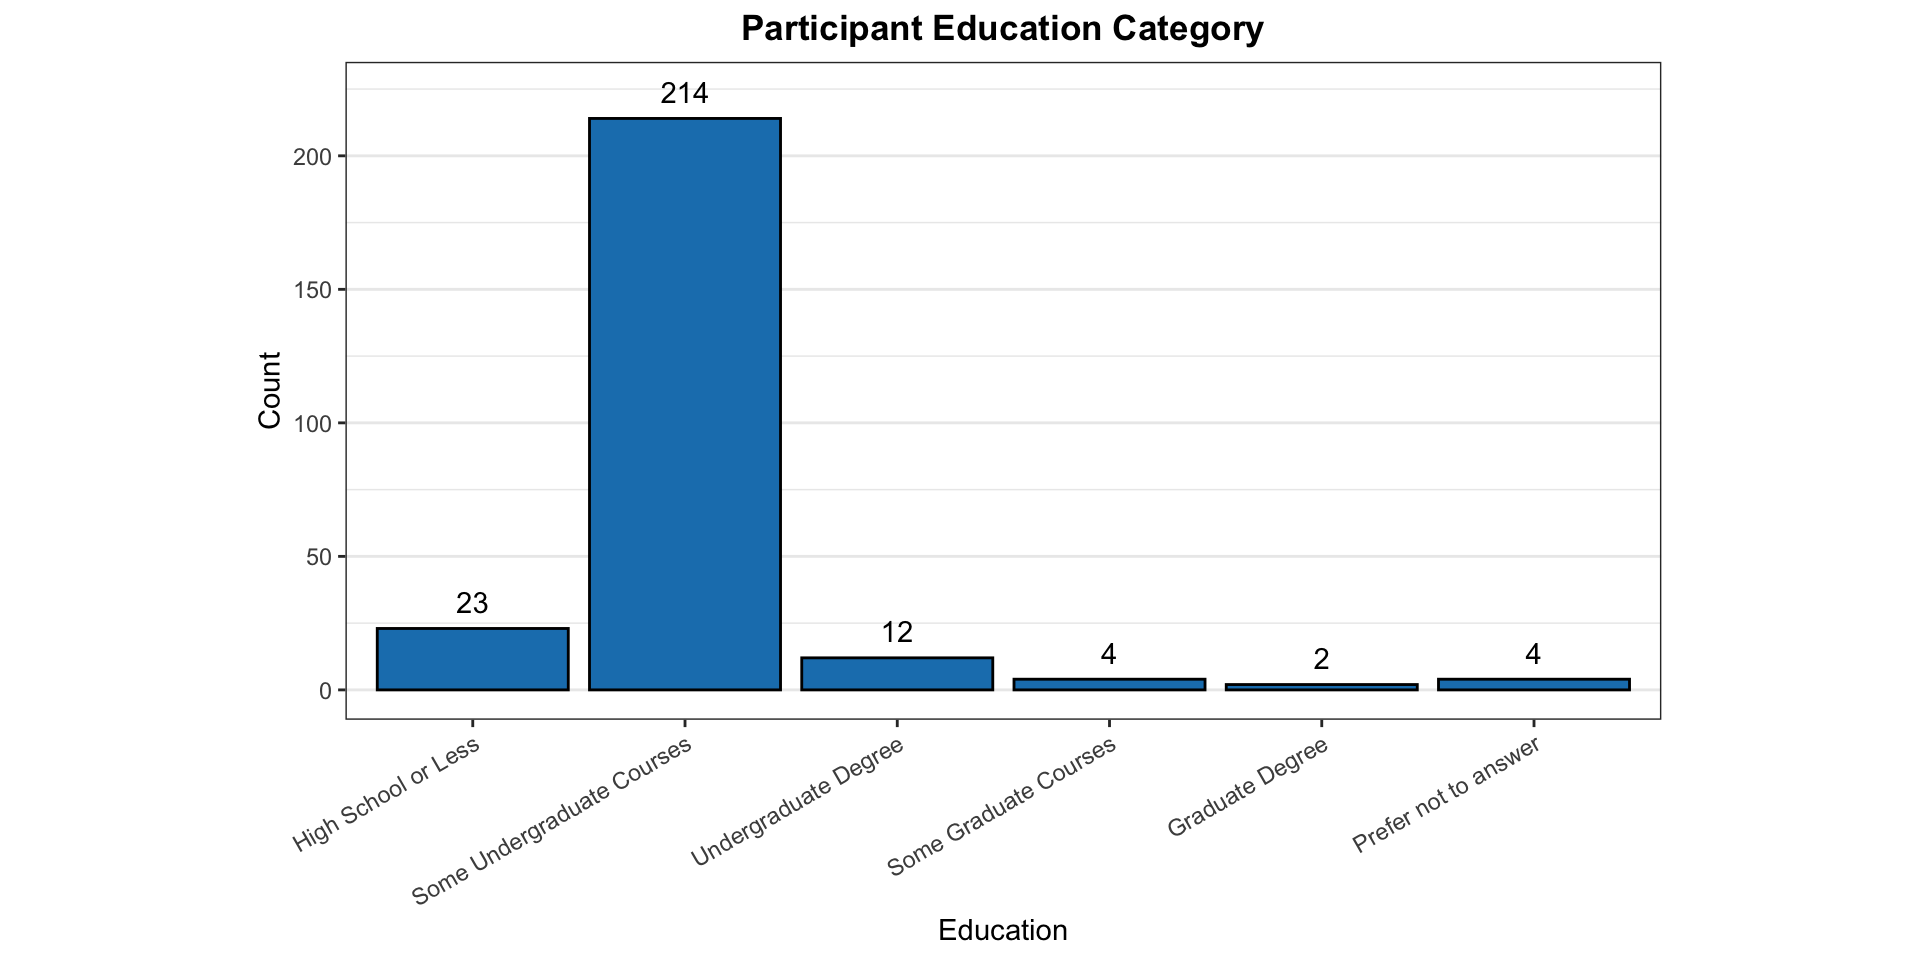
Figure 2: Histogram of experiment completion times. Online participants had generally shorter completion times due to a decreased number of trials.
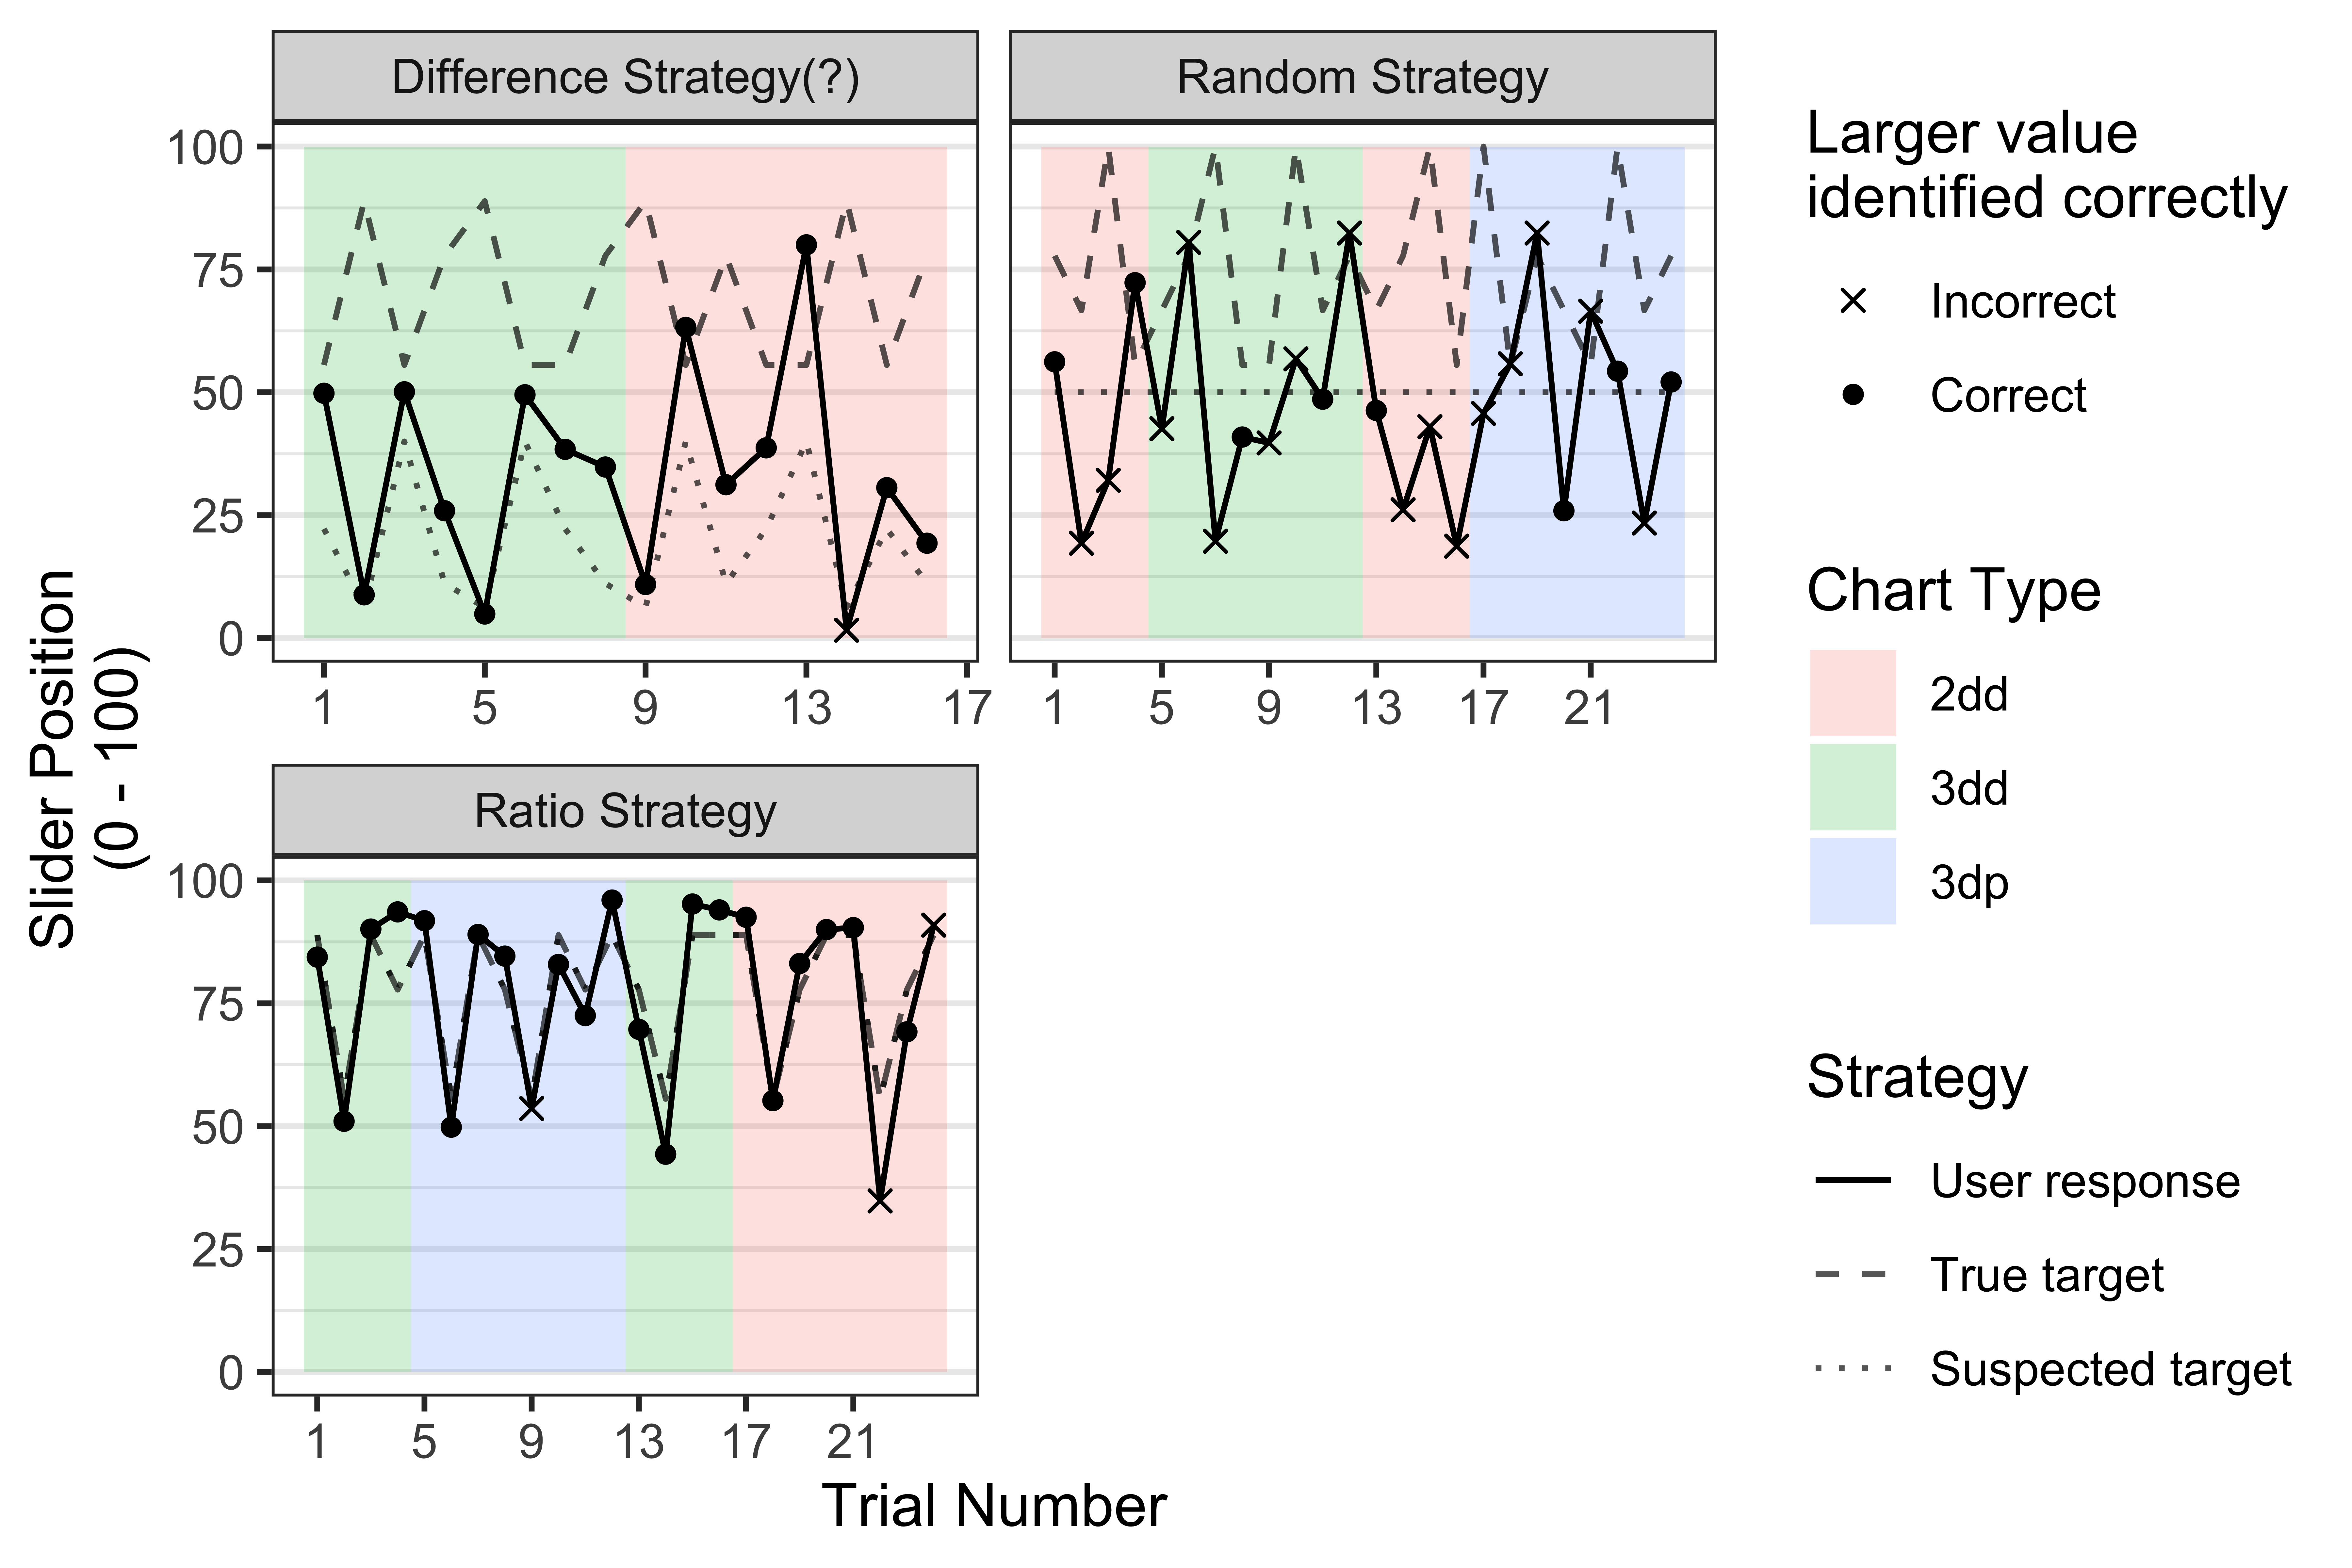
Figure 3: Three potential estimation strategies from participants. Many participants followed instructions to estimate ratios. However, some participants appeared to estimate the difference between stimuli pairs or submitted random values.
While careless respondents are an acknowledged issue, there is no general consensus on how to handle them.
Our first question was actually designed as a quasi-attention check! For each participant, we calculate p-values using a one-sided Binomial test:
\[ H_0: \pi\leq2/3\text{ vs. }H_1:\pi>2/3 \]
where \(\pi\) is the probability of correctly guessing the larger value.
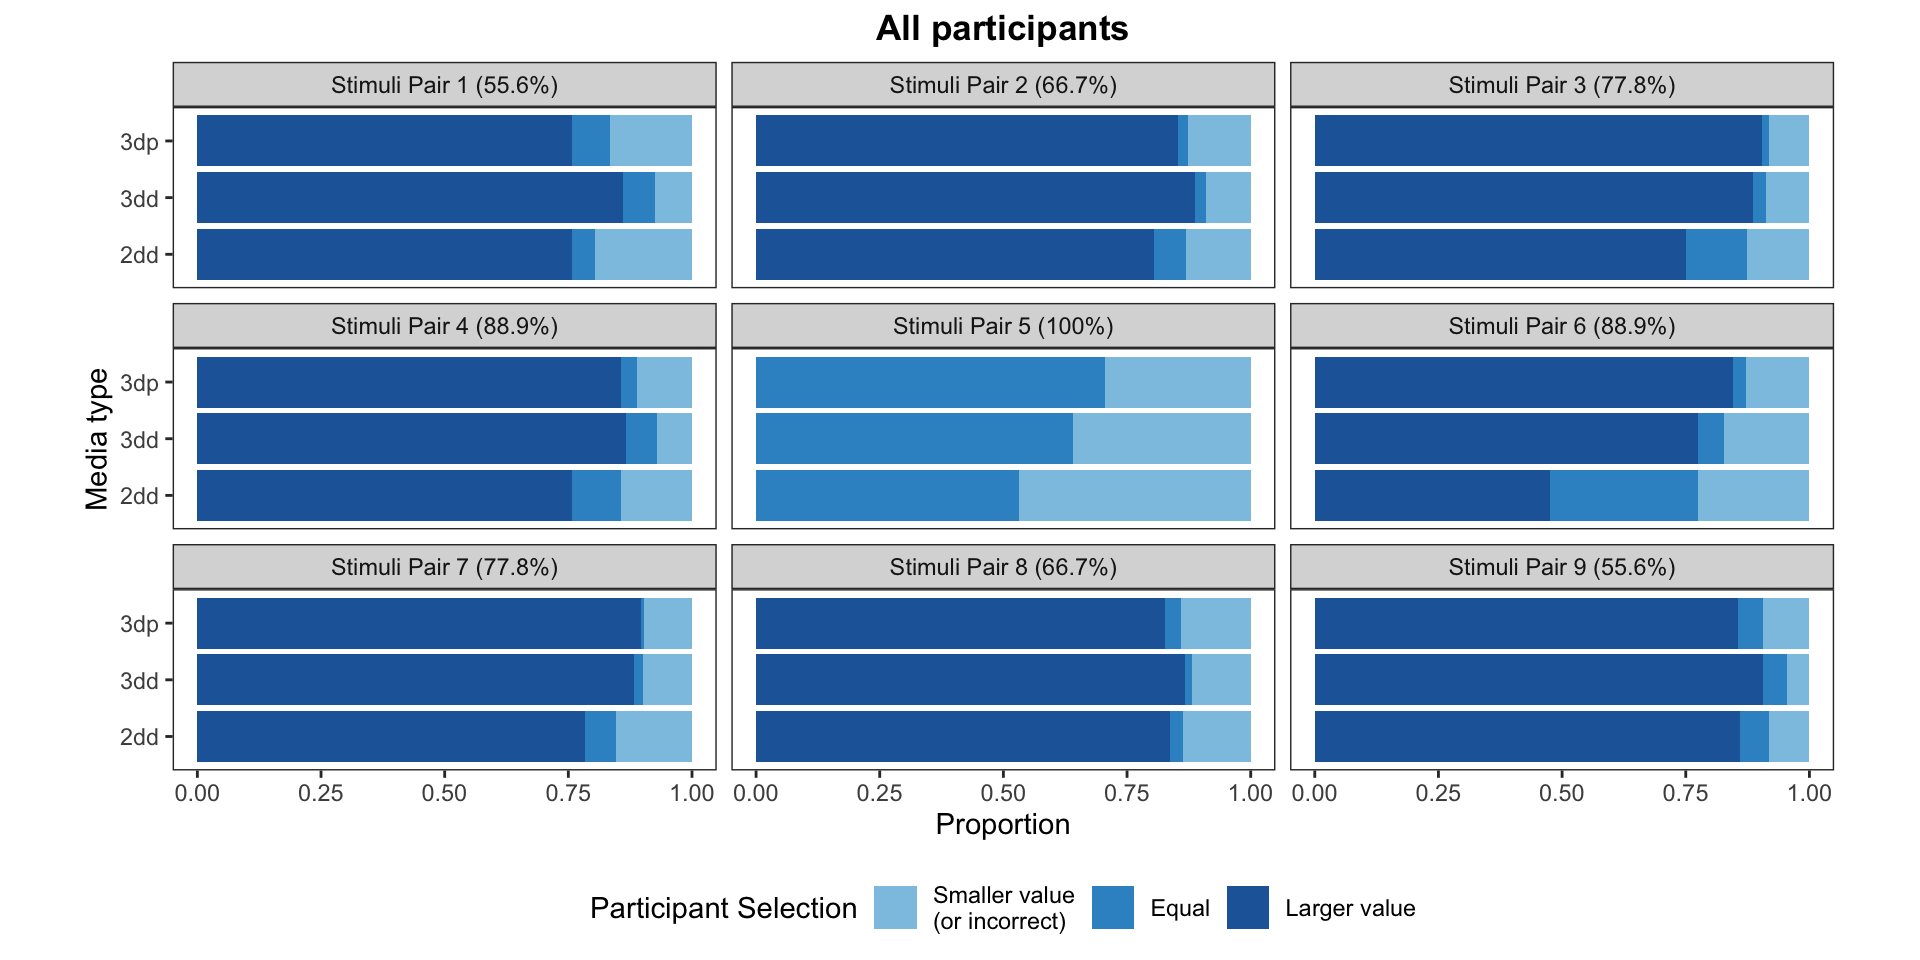
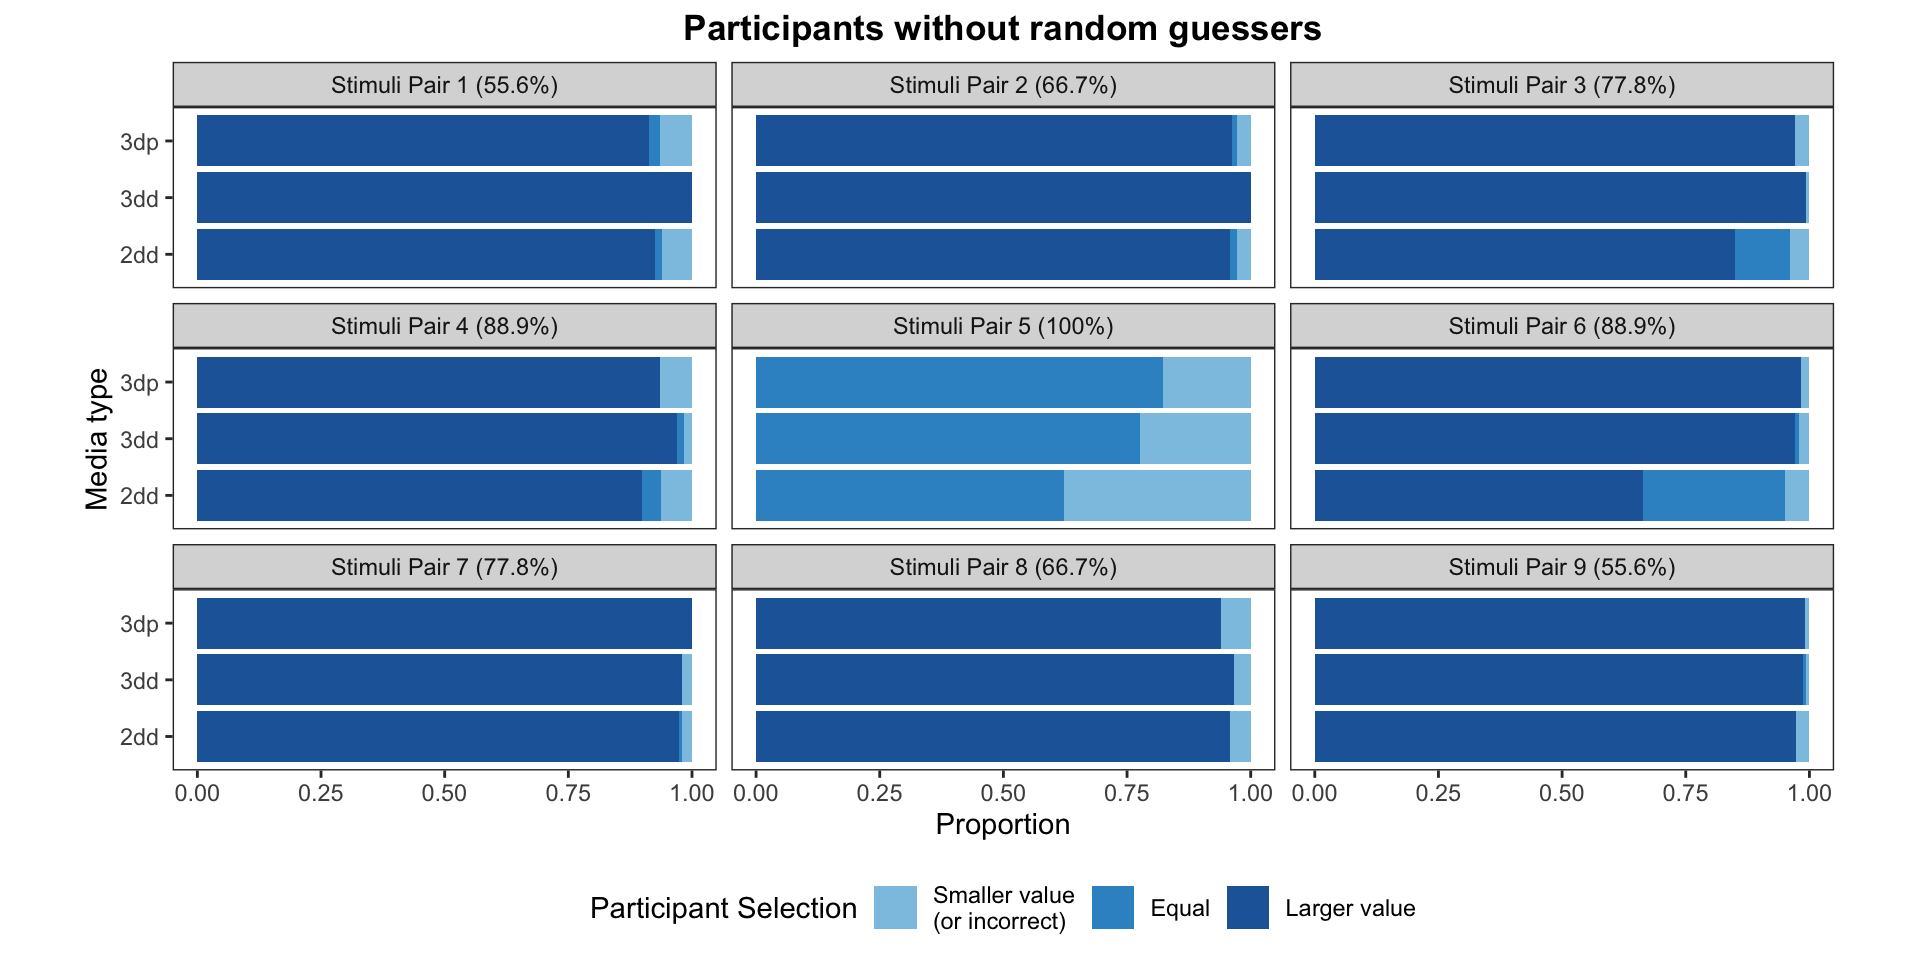
Was this participant answering Q1 correctly at least twice as often as incorrect options?
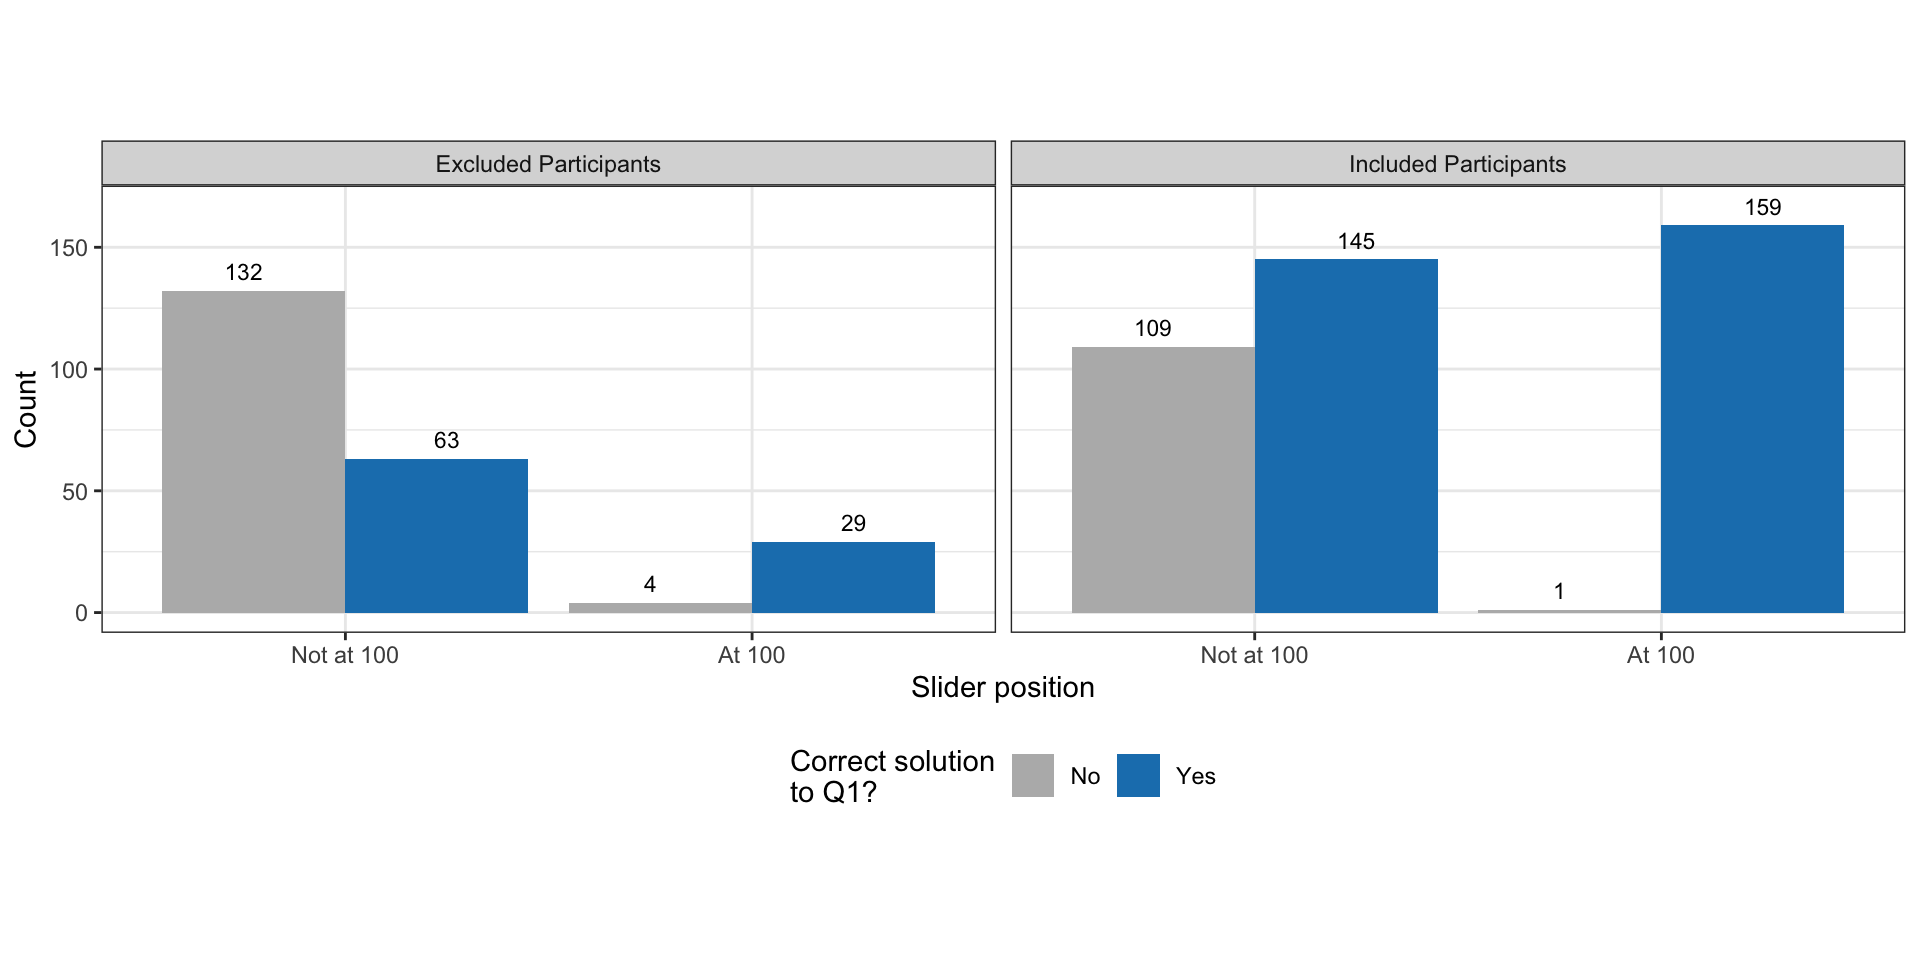
Figure 4: Proportion of correct responses to Question 1 with all participants
Figure 5: Proportion of correct responses to Question 1 without random guessers
We calculate error as follows:
\[ y=\log_2(|\text{User Response}-100\times(\text{True ratio})|+1/8) \]
We excluded:
Various models produced the same conclusions!
\[ Y_{ijklm}=\mu+S_i\times M_j\times P_k+\gamma_{lm}+\omega_{ijlm}+\epsilon_{ijklm} \]
where
| F | Df | Df.res | Pr(>F) | |
|---|---|---|---|---|
| (Intercept) | 332.257 | 1 | 2477.652 | 0.000 |
| set | 0.114 | 1 | 2745.681 | 0.735 |
| media | 3.189 | 2 | 2757.181 | 0.041 |
| pair_id | 1.919 | 7 | 2626.034 | 0.063 |
| set:media | 0.401 | 2 | 2747.072 | 0.669 |
| set:pair_id | 1.856 | 7 | 2681.555 | 0.073 |
| media:pair_id | 0.424 | 14 | 2661.569 | 0.968 |
| set:media:pair_id | 0.641 | 14 | 2669.463 | 0.833 |
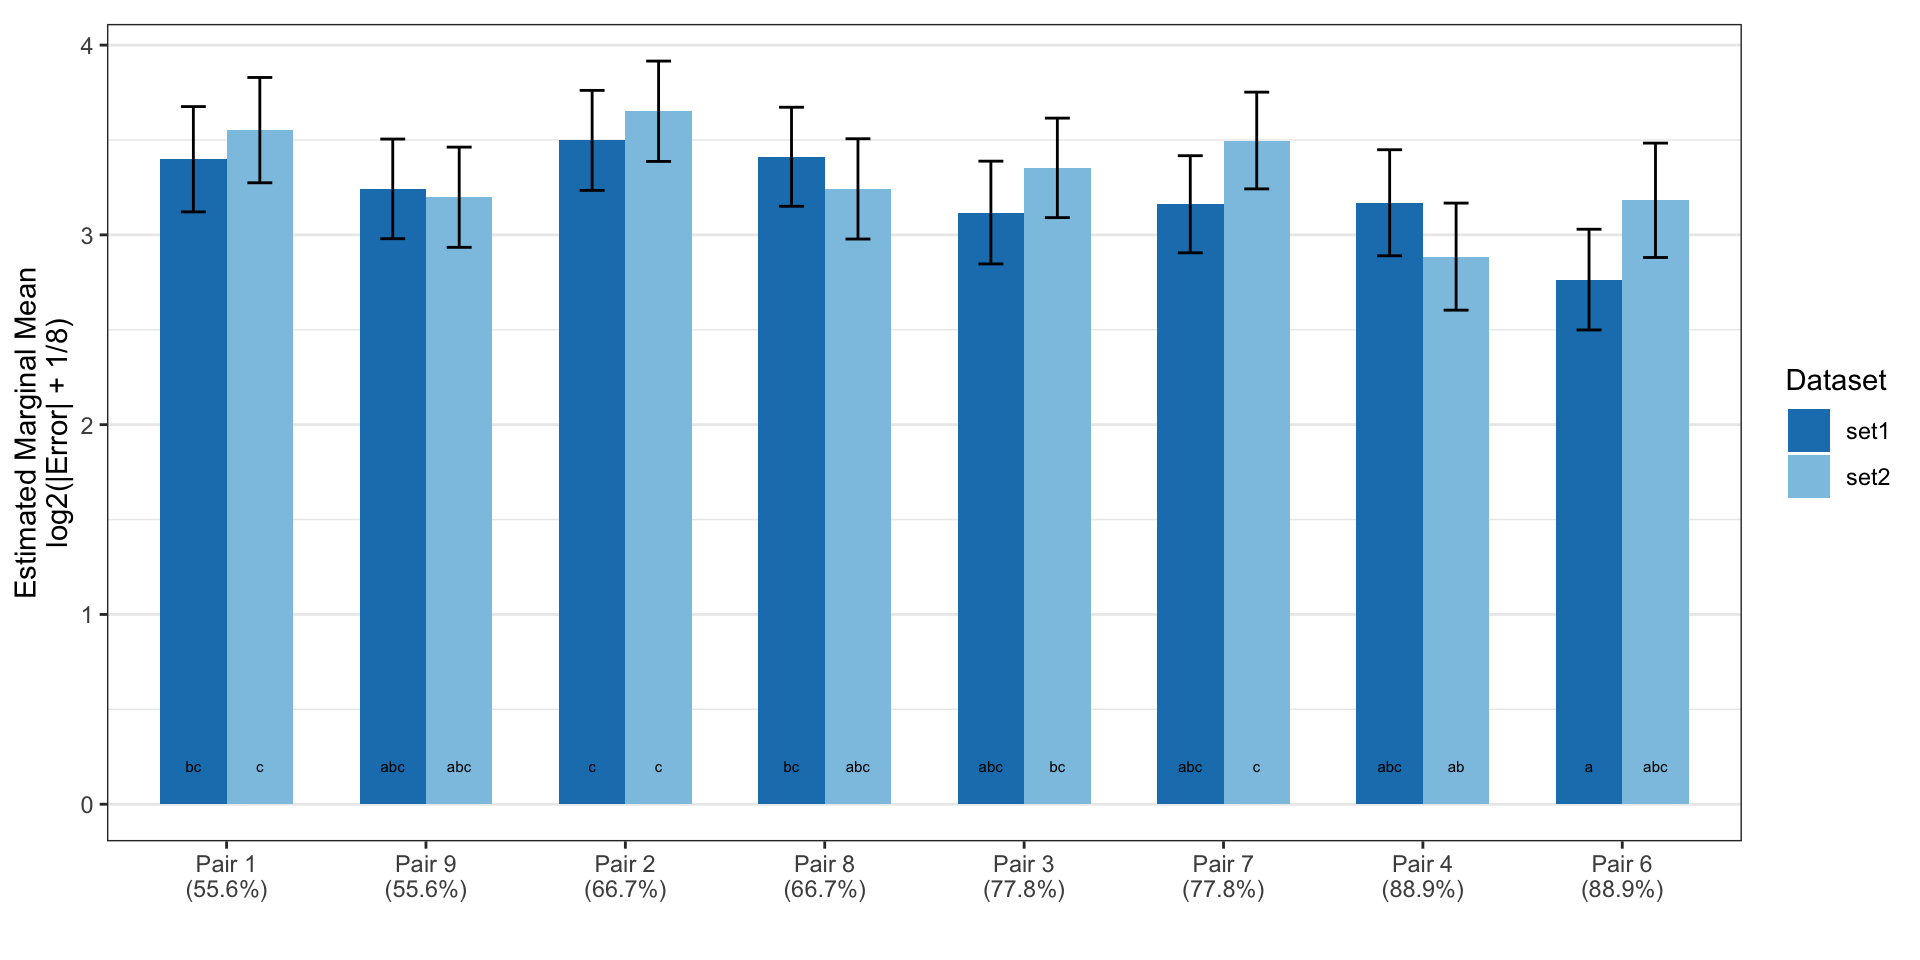
Figure 8: Estimated marginal means of stimuli pair and dataset. Bars sharing the same letter are not significantly different from one another.
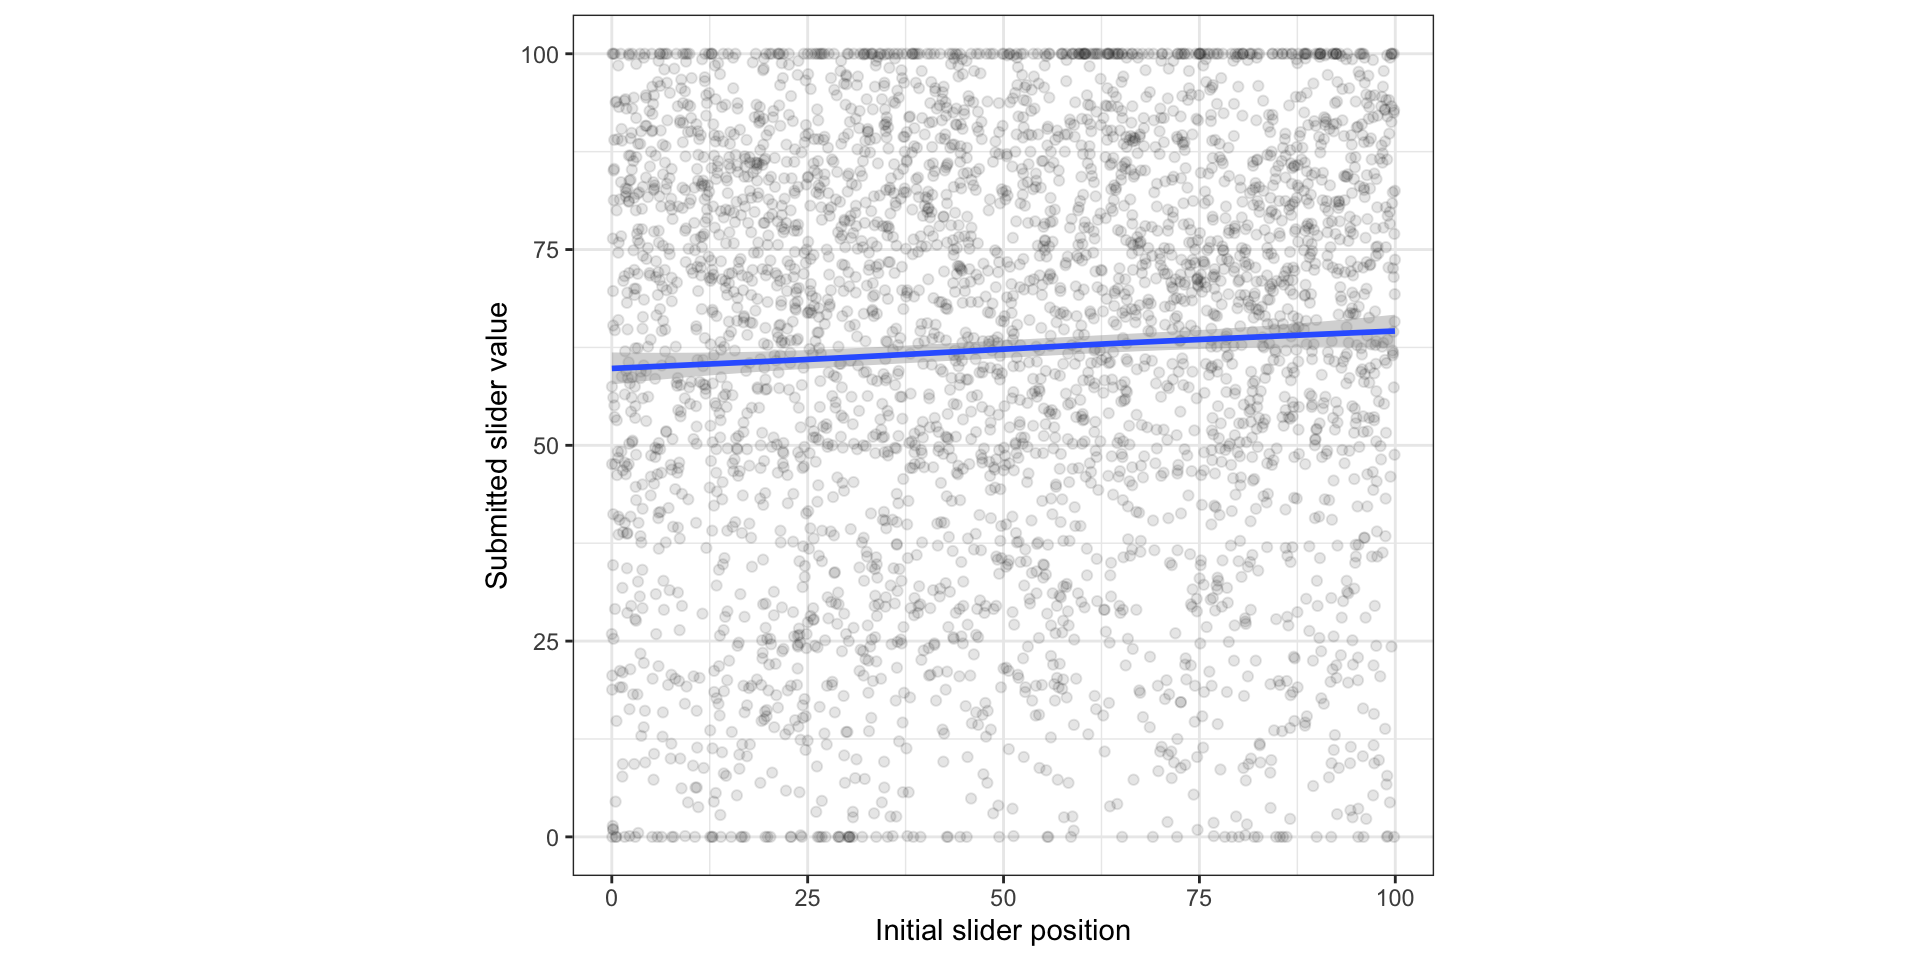
For each trial, the slider was randomly positioned between 0 and 100.
Figure 12: Effect of initial slider position on the submitted slider value.
We note the following results:
As one of the first studies to empirically evaluate physical 3D charts, there are many areas left to explore.
Study 1: Partial replication of Cleveland and McGill (1984) to compare digital and physical representations of bar charts.
No significant differences in ratio estimations detected from type of chart (\(n=38\))
Study 2: Students completed a series of reflections regarding their participation in the experiment.
What information do students learn from participating in an experiment, both as participants and consumers of scientific knowledge?
Many students connected ideas from the course material! (e.g., variable identification and generalizability)
Study 3: taking inspiration from Cleveland and McGill (1984) and Study 1, we extend our scope to use heat maps.
When all dimensions are used for conveying information, 3D heat maps produced lower error rates for estimations of ratios than 2D heat maps.
No detectable differences between digital and physical 3D heat maps.
| Term | All participants, all responses | All participants, Q1 correct | Filtered participants, all responses | Filtered participants, Q1 correct |
|---|---|---|---|---|
| set | 0.340 | 0.705 | 0.939 | 0.735 |
| media | 0.010 | 0.018 | 0.035 | 0.041 |
| pair_id | 0.244 | 0.333 | 0.089 | 0.063 |
| set:media | 0.297 | 0.711 | 0.543 | 0.669 |
| set:pair_id | 0.003 | 0.145 | 0.001 | 0.073 |
| media:pair_id | 0.815 | 0.740 | 0.982 | 0.968 |
| set:media:pair_id | 0.489 | 0.764 | 0.255 | 0.833 |
Figure 13: Interaction plots for media type and response filtering, facetted by stimuli pair and dataset.
Figure 14: Interaction plots for dataset and response filtering, facetted by stimuli pair and media type.
Figure 15: Interaction plots for stimuli pairs and response filtering, facetted by dataset and media type.
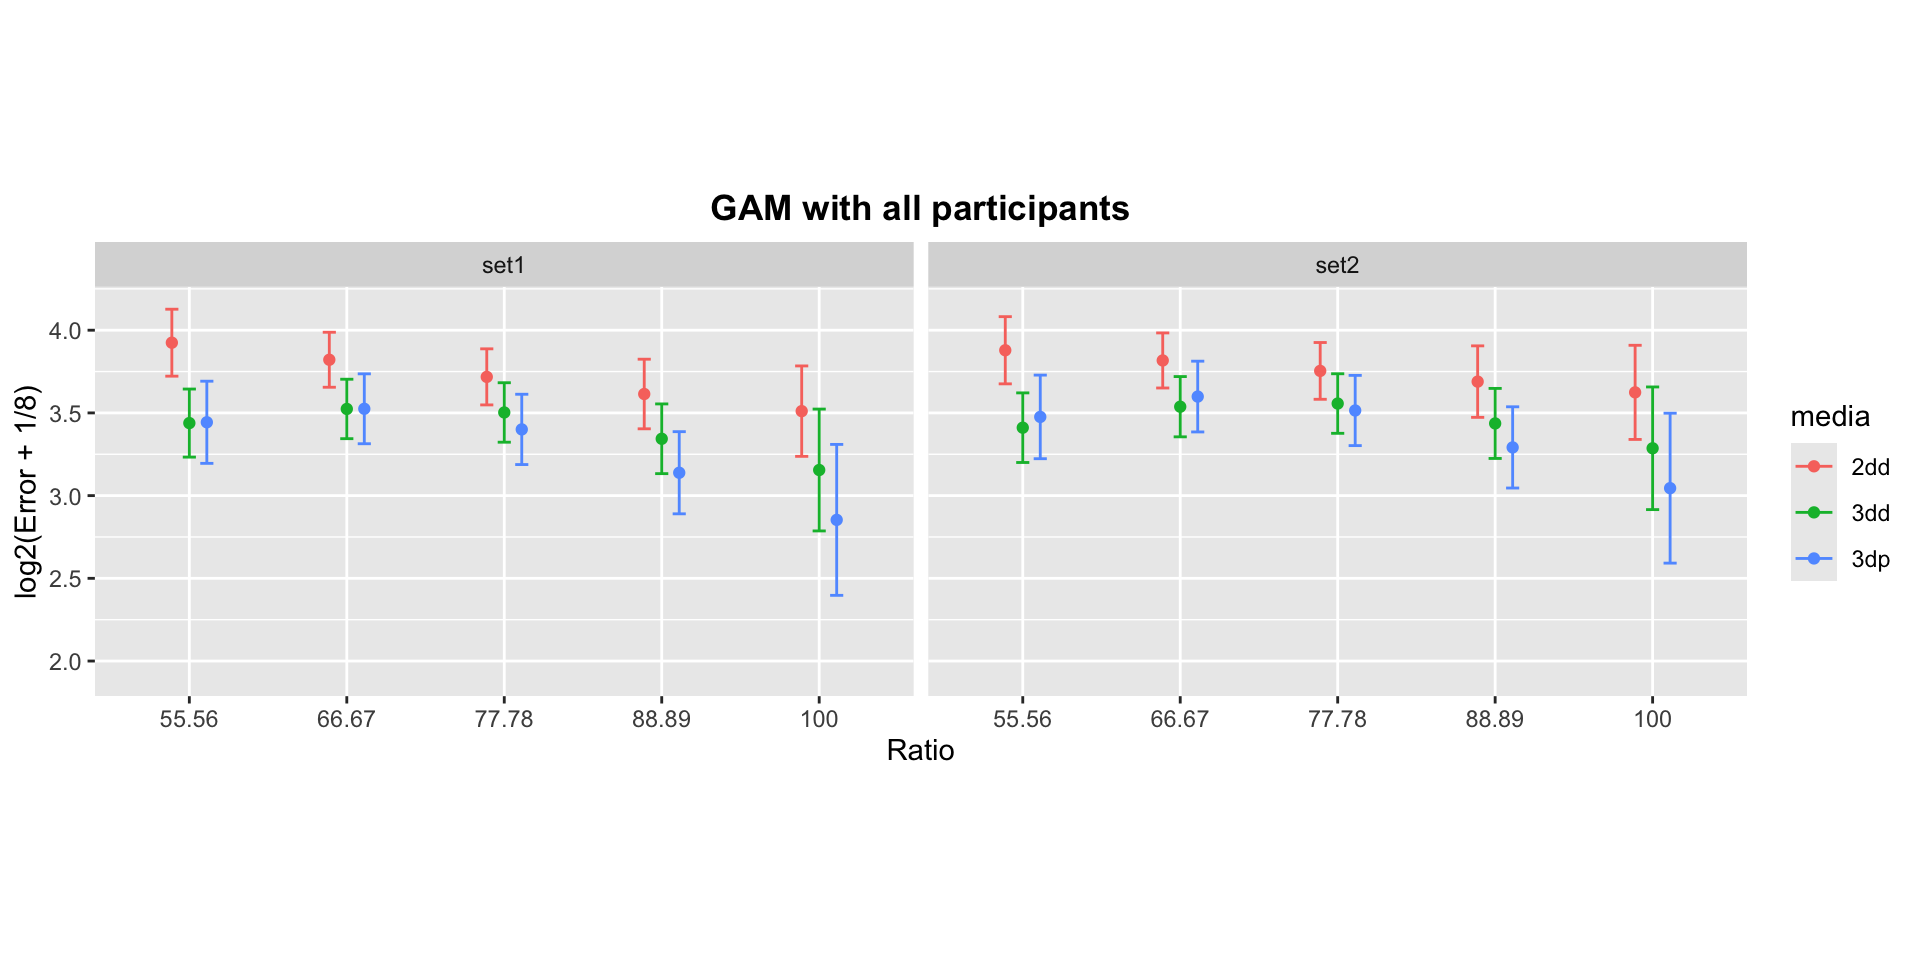
\[ y=\mu+S_i\times M_j + s_i^S(R)+s_j^M(R)+P_m+\epsilon \qquad(1)\]
where
\(y=\log_2(|\text{Error}|+1/8)\)
\(S_i\times M_j\) is the fixed effects for main effect and two-way interactions of dataset \(S_i\) and media type \(M_j\)
\(S_i^S(R)\) is a thin-plate spline function for ratio accounting for dataset
\(S_j^M(R)\) is a thin-plate spline function for ratio accounting for media type
\(P_m\) is the random effect of the \(m^{th}\) participant
\(\epsilon\) is random error
Family: gaussian
Link function: identity
Formula:
q2_error_cm ~ set * media + s(target_ratio, k = 4, by = media) +
s(target_ratio, k = 4, by = set) + s(user_id, bs = "re")
Parametric Terms:
df F p-value
set 1 0.030 0.863
media 2 12.190 5.29e-06
set:media 2 0.211 0.810
Approximate significance of smooth terms:
edf Ref.df F p-value
s(target_ratio):media2dd 1.002 1.003 0.058 0.813
s(target_ratio):media3dd 1.972 2.350 1.476 0.200
s(target_ratio):media3dp 1.047 1.428 1.612 0.268
s(target_ratio):setset1 1.005 1.009 0.650 0.422
s(target_ratio):setset2 1.022 1.042 0.165 0.719
s(user_id) 217.826 258.000 6.423 <2e-16
Family: gaussian
Link function: identity
Formula:
q2_error_cm ~ set * media + s(target_ratio, k = 4, by = media) +
s(target_ratio, k = 4, by = set) + s(user_id, bs = "re")
Parametric Terms:
df F p-value
set 1 0.279 0.598
media 2 13.634 1.28e-06
set:media 2 0.450 0.638
Approximate significance of smooth terms:
edf Ref.df F p-value
s(target_ratio):media2dd 3.368e-04 6.524e-04 0.186 0.991204
s(target_ratio):media3dd 1.006e+00 1.011e+00 2.510 0.111735
s(target_ratio):media3dp 1.011e+00 1.022e+00 0.791 0.369414
s(target_ratio):setset1 2.232e+00 2.599e+00 7.748 0.000327
s(target_ratio):setset2 2.349e+00 2.702e+00 6.397 0.000404
s(user_id) 1.396e+02 1.600e+02 7.105 < 2e-16
Ph.D. Final Examination